 Today's AI Tip
Shortening an update with AI? Ask what it left out.
It reads fine, so you send it
It's easy to paste the update, ask for a shorter version, skim it and send it. It reads fine, so what's missing is easy to miss.
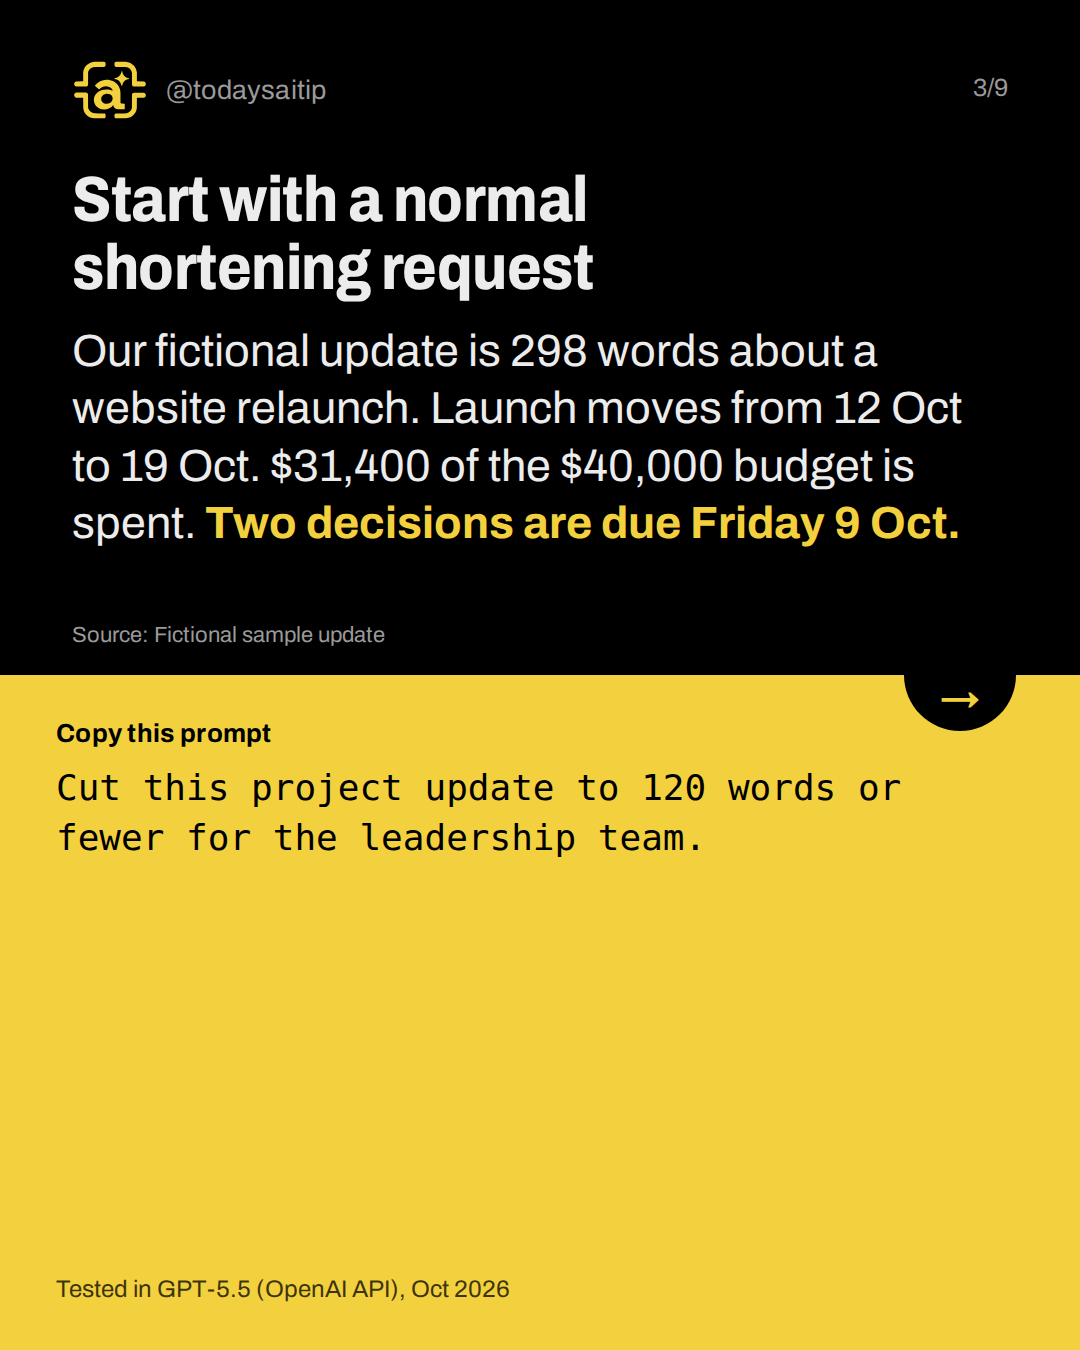
Start with a normal shortening request
Tested in GPT-5.5 (OpenAI API), Oct 2026
Our fictional update is 298 words about a website relaunch. Launch moves from 12 Oct to 19 Oct. $31,400 of the $40,000 budget is spent. Two decisions are due Friday 9 Oct.
Source: Fictional sample update
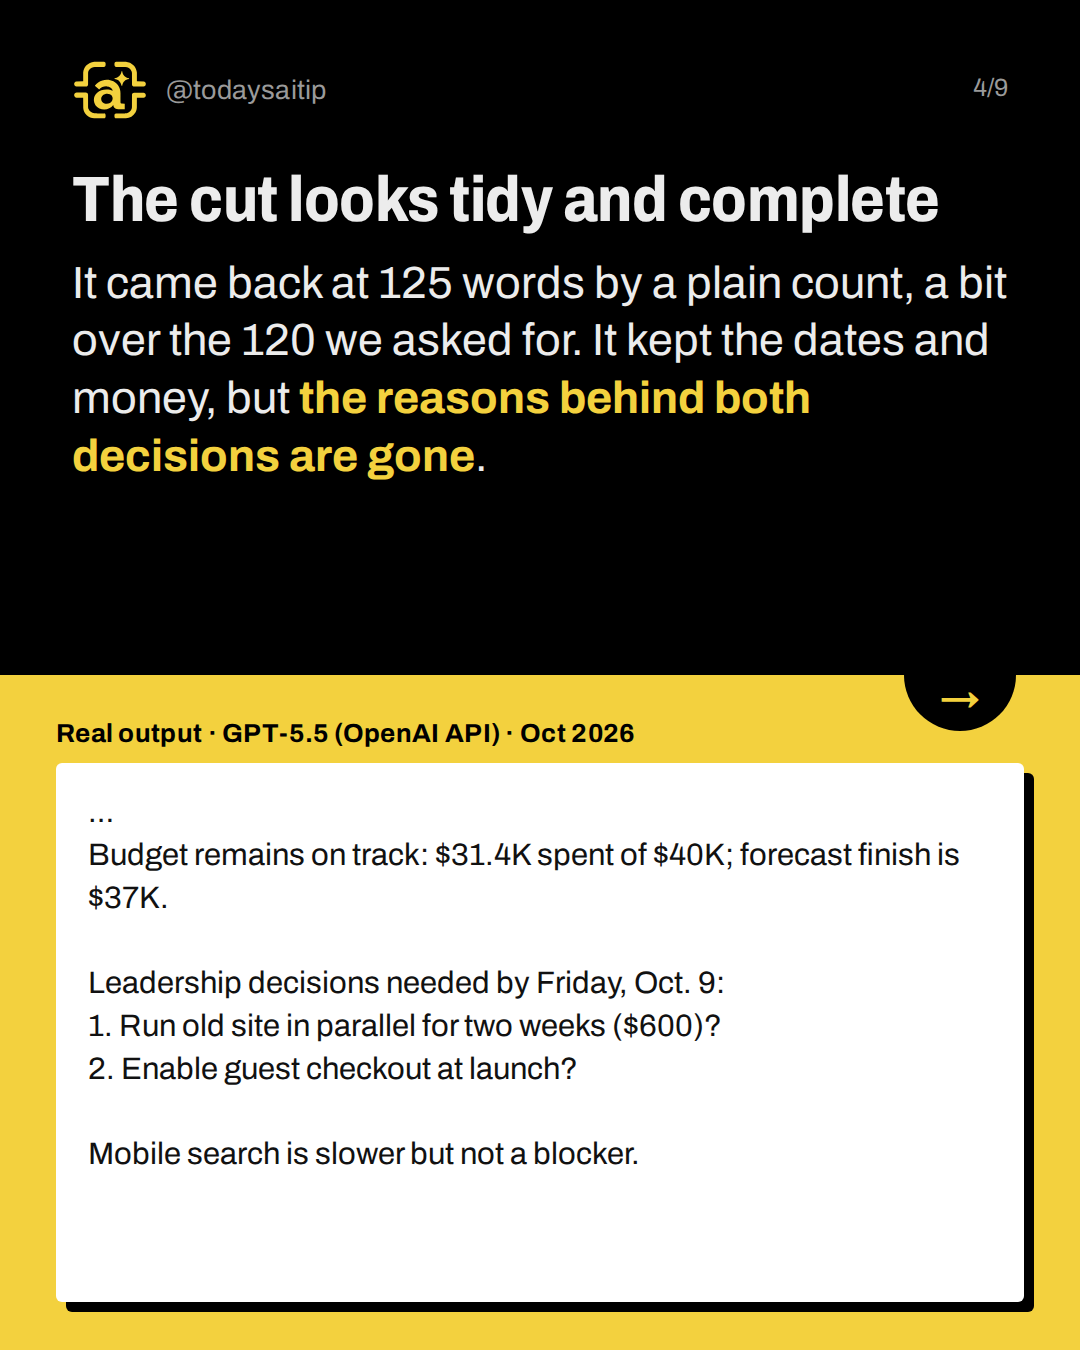
The cut looks tidy and complete
Real output · GPT-5.5 (OpenAI API) · Oct 2026
It came back at 125 words by a plain count, a bit over the 120 we asked for. It kept the dates and money, but the reasons behind both decisions are gone.
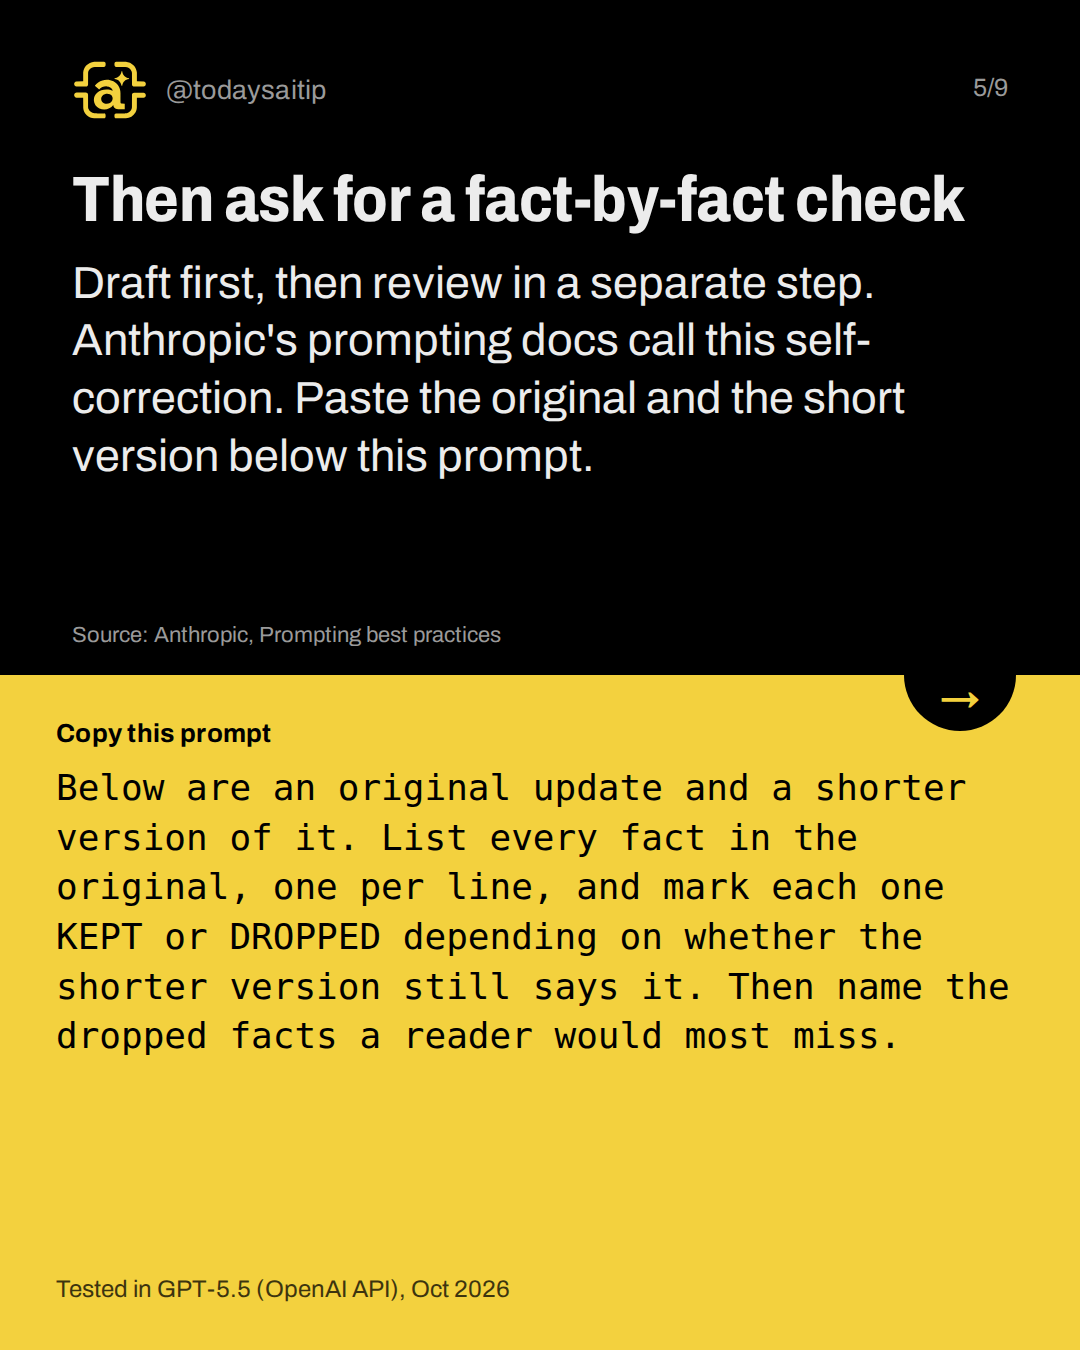
Then ask for a fact-by-fact check
Tested in GPT-5.5 (OpenAI API), Oct 2026
Draft first, then review in a separate step. Anthropic's prompting docs call this self-correction. Paste the original and the short version below this prompt.
Source: Anthropic, Prompting best practices
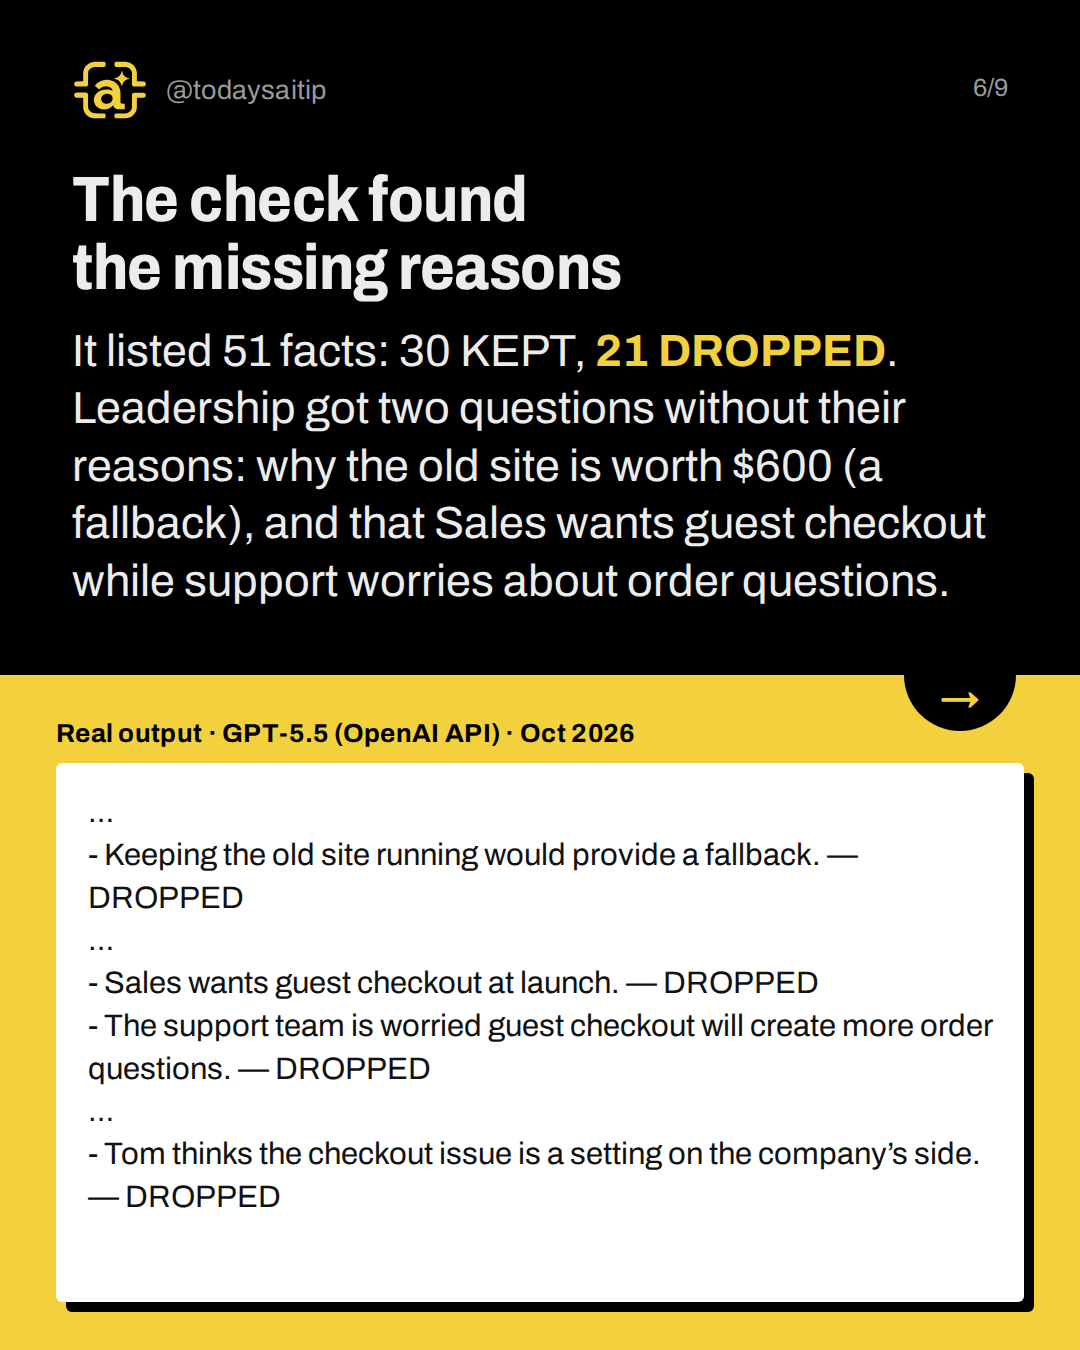
The check found the missing reasons
Real output · GPT-5.5 (OpenAI API) · Oct 2026
It listed 51 facts: 30 KEPT, 21 DROPPED. Leadership got two questions without their reasons: why the old site is worth $600 (a fallback), and that Sales wants guest checkout while support worries about order questions.
The check isn't perfect either
In our hand check, the marks held up except one: 'Priya found the 9 broken links' was marked KEPT, but the short version says 'QA' and never names Priya. The list of facts readers would most miss also led with the company name. Use it to find gaps, then judge them yourself.
Put back what a decision needs
Put back the dropped facts a decision depends on, then send. With real updates, remove names, account numbers and other personal details first, and check the tool's data policy or your employer's approved tools.
Try it: Run both prompts on the next update you shorten.
Sources and assumptions
- Anthropic, Prompting best practices (Claude Platform Docs): Under 'Chain complex prompts': 'The most common chaining pattern is self-correction: generate a draft → have Claude review it against criteria → have Claude refine based on the review.' The post uses this principle (a separate review step after the draft). The page is written for Claude; we ran the test in GPT-5.5, so the post applies the principle and does not claim the doc covers GPT-5.5. (checked 2026-10-04)
- OpenAI API docs, GPT-5.5 model page: GPT-5.5 is available in the OpenAI API (default snapshot gpt-5.5-2026-04-23), and medium is the default reasoning effort. Our runs used the API defaults, so the label 'GPT-5.5 (OpenAI API)' is accurate. (checked 2026-10-04)
Assumptions:
- The sample update is fictional (Larkfield Garden Supply, Priya, Tom, Aisha and Dana are invented). It is 298 words by a hand whitespace count, including the subject line and sign-off.
- Both prompts ran in GPT-5.5 through the OpenAI Chat Completions API with default settings (no system message, default reasoning effort, which the docs say is medium), on 2026-10-05 UTC (2026-10-04 US time). Run results are in record.tests, ids 'cut' and 'whats-missing'.
- The Claude runs (ids 'cut' and 'ping', tool claude) failed in the research session because the claude -p call errored, so no Claude output exists. The slides must not name Claude as a tested tool, and prompt_tools should say only 'Tested in GPT-5.5 (OpenAI API), Oct 2026'.
- Word count of the cut: 125 by a plain whitespace count including the 5-word heading and the list numbers '1.' and '2.'; 118 without them. The slide should say 'about 120 words (125 by a plain count)' or leave the count out. It must not say 'under 120'.
- The check found 51 facts, 30 KEPT and 21 DROPPED (counted by hand from the output). Our hand check found no fact marked KEPT that was actually missing. The one inconsistency: 'Priya checked the first 50 product pages' is marked DROPPED and 'Priya found broken image links on 9 of the first 50 pages' is marked KEPT, though the short version names neither Priya nor who did the check ('QA found 9 broken image links in the first 50').
- Results come from one run each. A rerun can produce a different cut and different drops.
The short version
- A shorter update can silently lose facts.
- Ask for a KEPT or DROPPED list.
- Put back what a decision depends on.
- Hand-check the marks before you send.