 Today's AI Tip
A Friday status template I tested. It filed my lunch as Done.
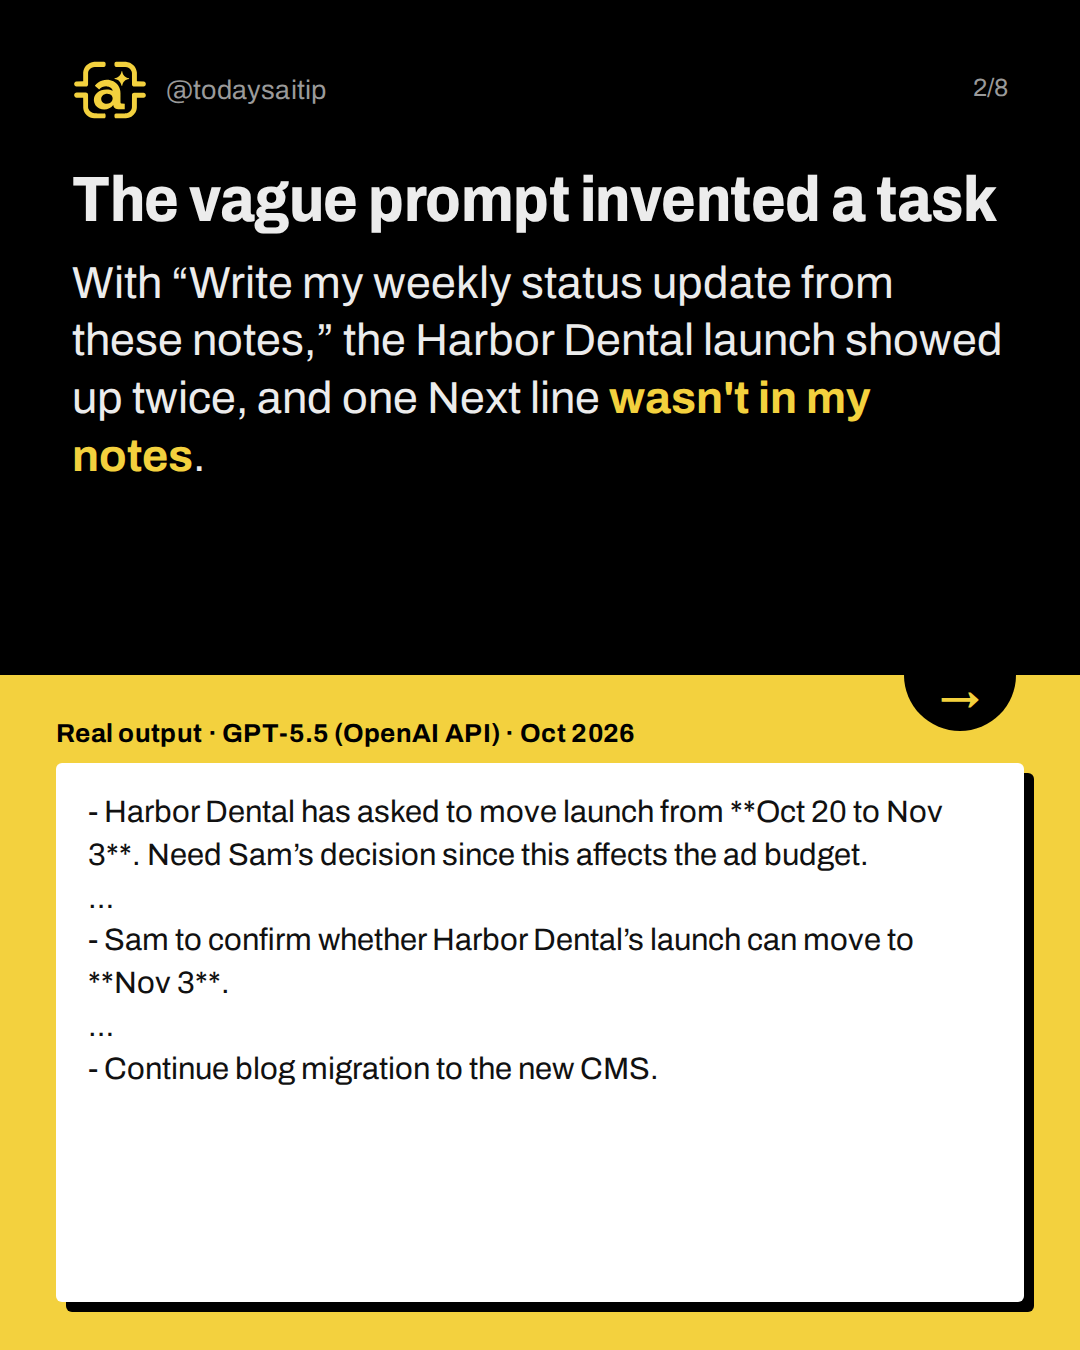
The vague prompt invented a task
Real output · GPT-5.5 (OpenAI API) · Oct 2026
With “Write my weekly status update from these notes,” the Harbor Dental launch showed up twice, and one Next line wasn't in my notes.
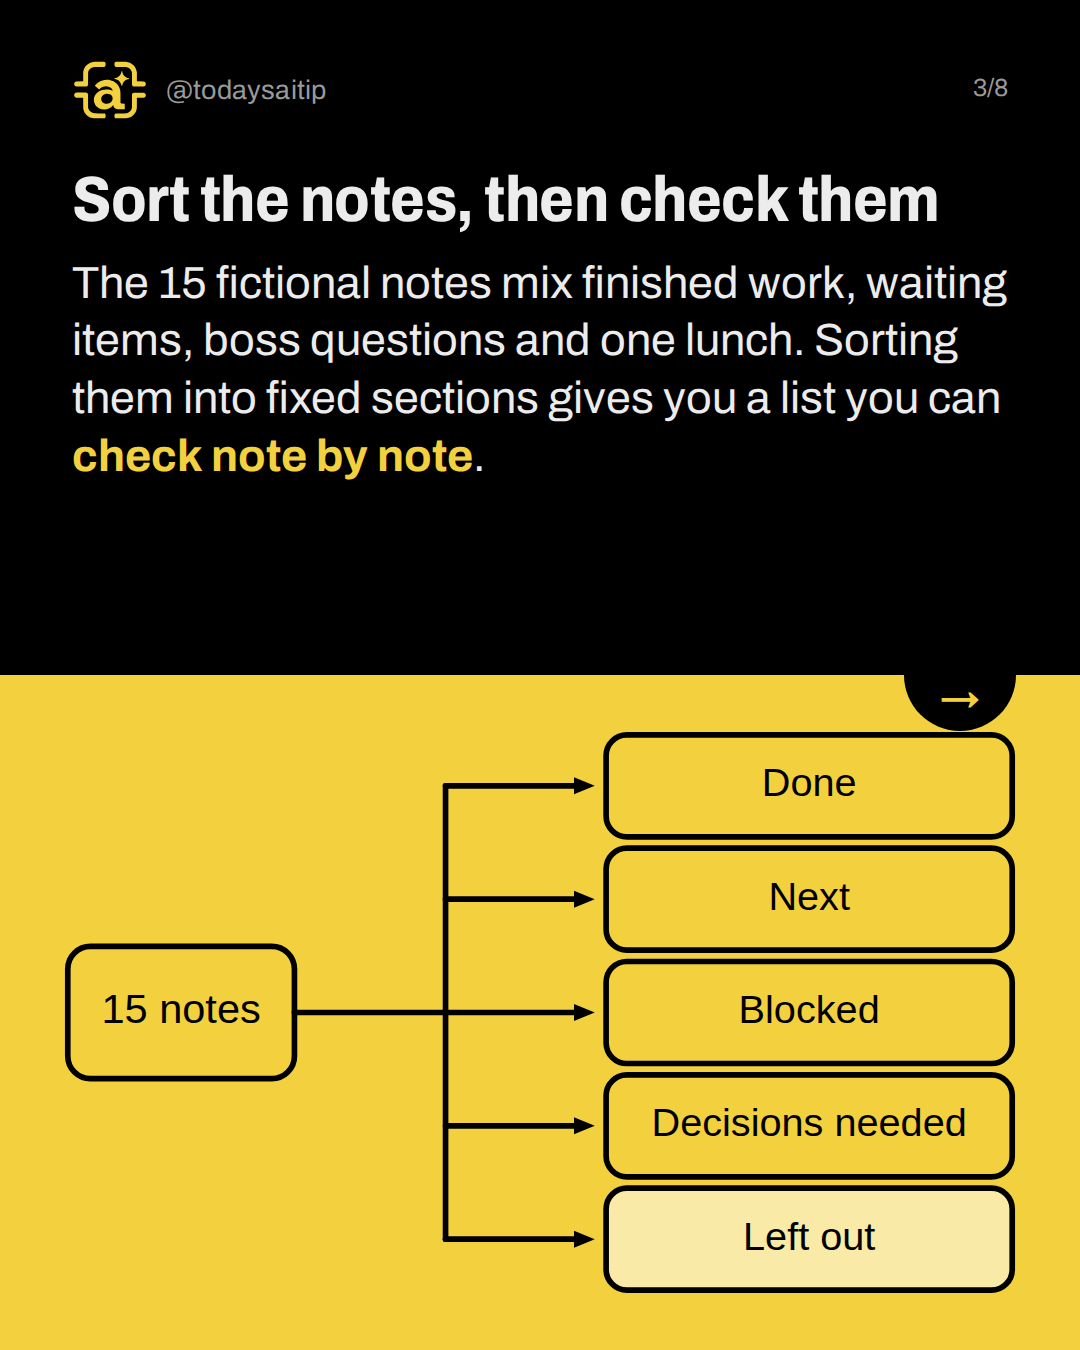
Sort the notes, then check them
The 15 fictional notes mix finished work, waiting items, boss questions and one lunch. Sorting them into fixed sections gives you a list you can check note by note.
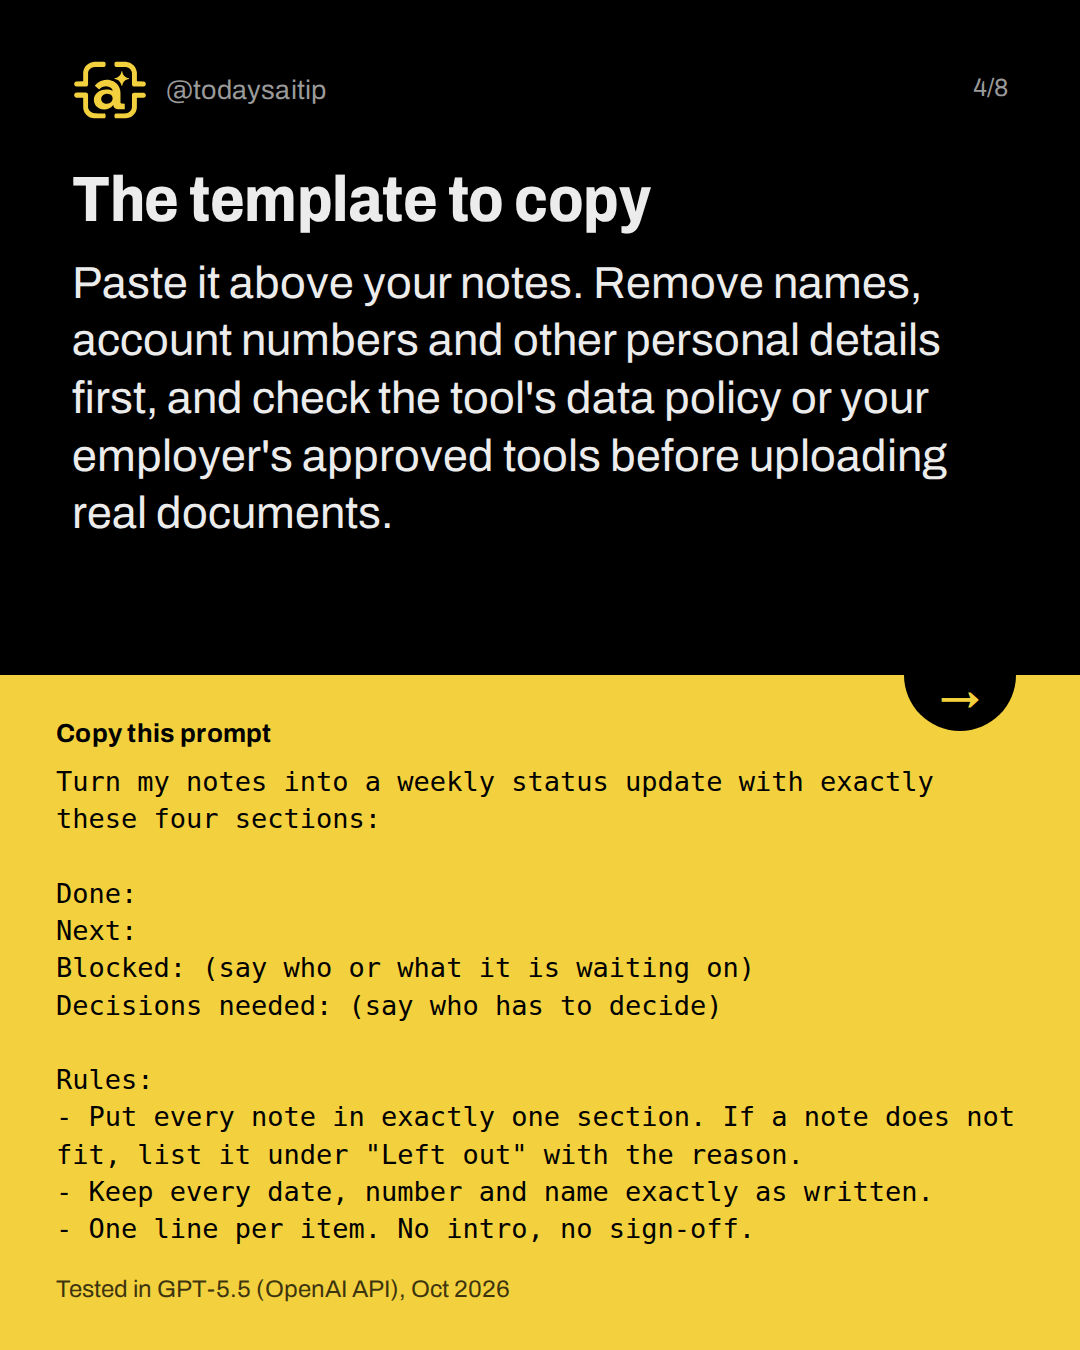
The template to copy
Tested in GPT-5.5 (OpenAI API), Oct 2026
Paste it above your notes. Remove names, account numbers and other personal details first, and check the tool's data policy or your employer's approved tools before uploading real documents.
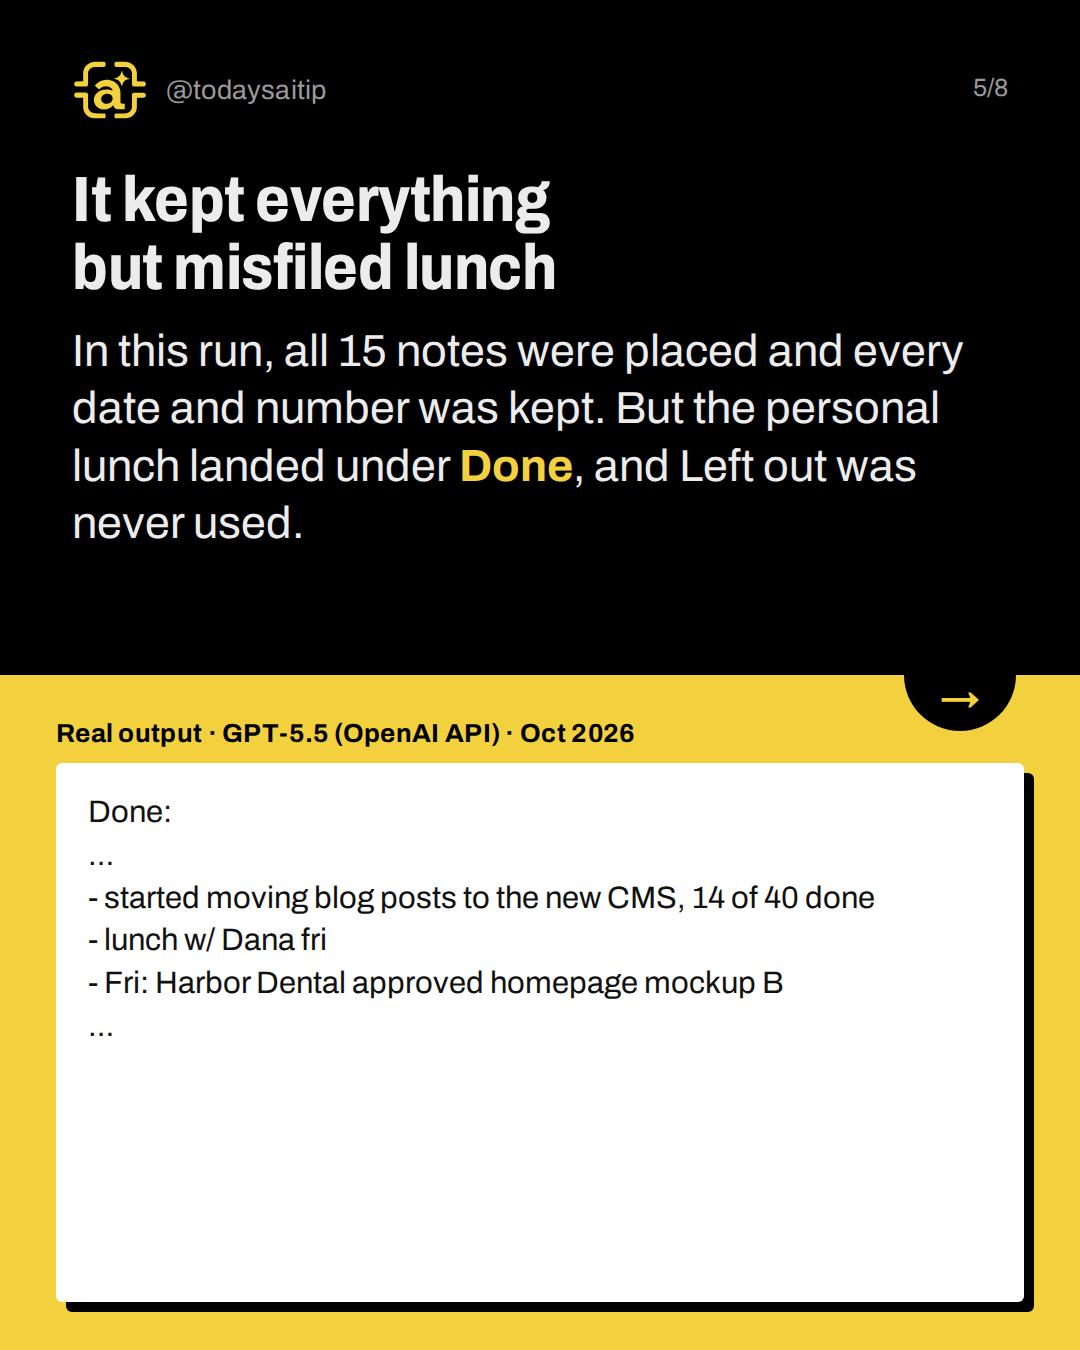
It kept everything but misfiled lunch
Real output · GPT-5.5 (OpenAI API) · Oct 2026
In this run, all 15 notes were placed and every date and number was kept. But the personal lunch landed under Done, and Left out was never used.
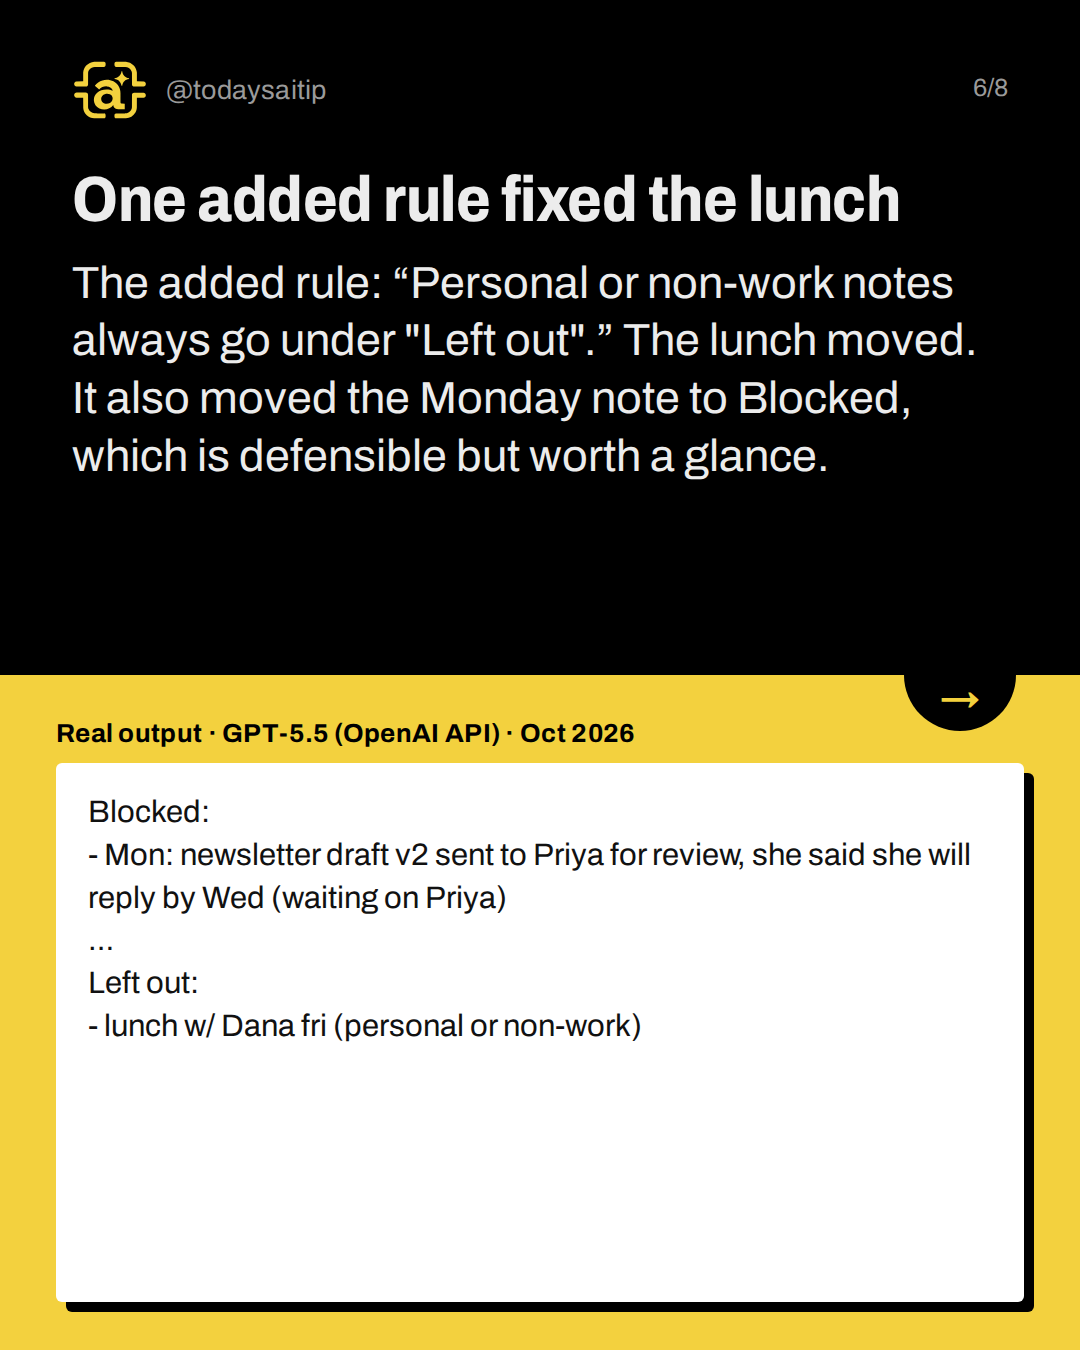
One added rule fixed the lunch
Real output · GPT-5.5 (OpenAI API) · Oct 2026
The added rule: “Personal or non-work notes always go under "Left out".” The lunch moved. It also moved the Monday note to Blocked, which is defensible but worth a glance.
Read the Done list first
Before you send, read the Done list line by line. It's the list your boss believes, and in this test it's where the misfile was.
Try it: Paste this Friday's notes into the template and read Done first.
Sources and assumptions
- Prompting best practices, Claude Platform Docs (Anthropic): General principle behind the template: "Be specific about the desired output format and constraints." and "Provide instructions as sequential steps using numbered lists or bullet points when the order or completeness of steps matters." Also: "Claude responds well to clear, explicit instructions. Being specific about your desired output can help enhance results." (vendor guidance written for Claude; it does not discuss status templates or GPT-5.5) (checked 2026-10-05)
- GPT-5.5 model page, OpenAI API docs: GPT-5.5 is an OpenAI API model (snapshot gpt-5.5-2026-04-23) available on Chat Completions; reasoning.effort defaults to medium. This backs the 'GPT-5.5 (OpenAI API)' label and the settings used. (checked 2026-10-05)
Assumptions:
- All notes, people (Priya, Sam, Dana) and clients (Harbor Dental, Mill Street, Okafor Legal) are fictional; no real data was used.
- Each prompt was run exactly once, on 2026-10-05 (2026-10-06 02:08–02:09 UTC), through engine/ai-test.js. Another run could sort the notes differently, so the misfile is what happened in this test, not a guaranteed behavior.
- Settings: OpenAI Chat Completions, model gpt-5.5, one user message (prompt + notes), no system message, no temperature or reasoning_effort set, so the documented defaults applied (reasoning effort medium).
- The Claude runs ('before' and 'template', tool claude) FAILED inside this research session (the nested claude -p call errored) and have output null in tests.json. They must not be quoted, and the post must not claim the template was tested in Claude. Only the three GPT-5.5 runs (before-gpt, template-gpt, template-fixed-gpt) count.
- Ground truth for scoring (my own key, set before the run): Done = signup link fix, ad spend report, Harbor mockup B approved, invoice #2207 paid, Mon newsletter sent (or Blocked, both defensible), CMS 14 of 40 (Done as partial progress); Next = case studies, expense report Oct 10; Blocked = Priya approval for Oct 8 send, photographer Oct 9, Okafor Legal GA login; Decisions = Harbor launch move (Sam), Canva renewal (Sam), standup frequency (team); Left out = lunch w/ Dana fri (personal).
- Scoring of template-gpt: 15 of 15 notes present, 0 dropped, 1 misfiled (lunch w/ Dana fri under Done), no dates or numbers changed. It mostly copied the notes word for word (including 'Mon:' prefixes and '??'), so the output is accurate but not polished.
- Scoring of template-fixed-gpt: 15 of 15 present, 0 dropped, lunch correctly under Left out; it moved the Monday 'sent to Priya' note to Blocked, which I count as defensible, not a misfile.
- Scoring of before-gpt: personal lunch omitted (fine), Harbor Dental launch listed twice (under waiting and under decisions), and one invented line 'Continue blog migration to the new CMS.' under Next week (inferred, not in the notes); dates and numbers kept.
The short version
- Sort notes into four sections plus Left out
- In this test, 15 of 15 notes were placed
- One misfile: lunch landed under Done
- One added rule moved it to Left out
- Read Done before you send