 Today's AI Tip
AI checked its draft against my checklist. Then it cut the free loaf.
Let the AI review its own draft
Anthropic's prompting guide calls its most common chaining pattern self-correction: draft, review against criteria, then refine. I tried it on a job posting.
Source: Anthropic, Prompting best practices
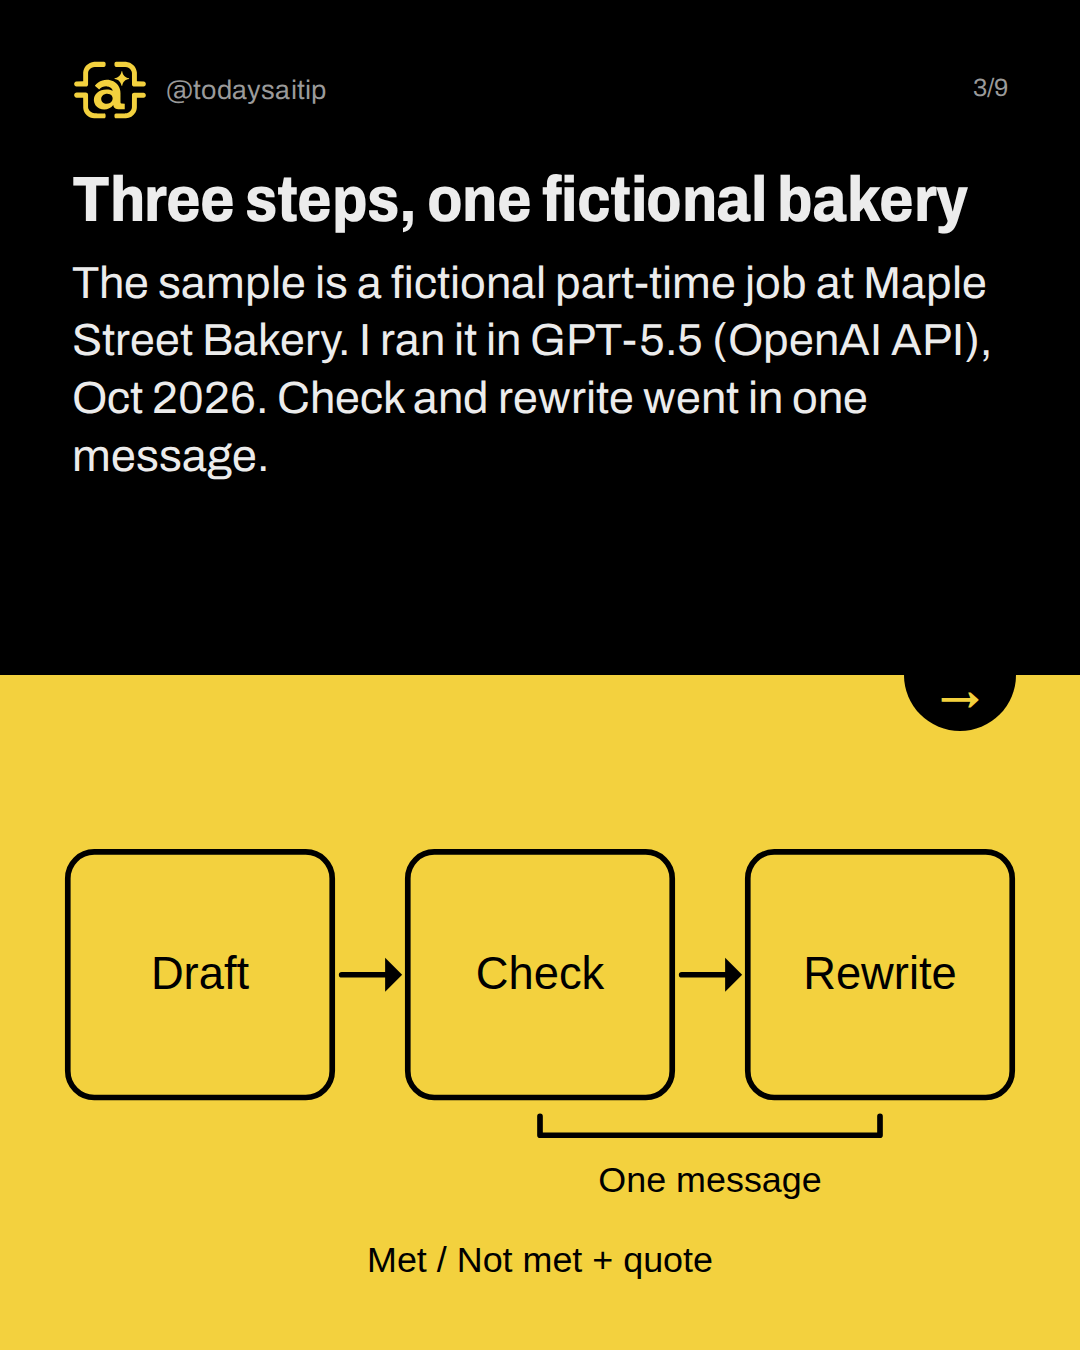
Three steps, one fictional bakery
The sample is a fictional part-time job at Maple Street Bakery. I ran it in GPT-5.5 (OpenAI API), Oct 2026. Check and rewrite went in one message.
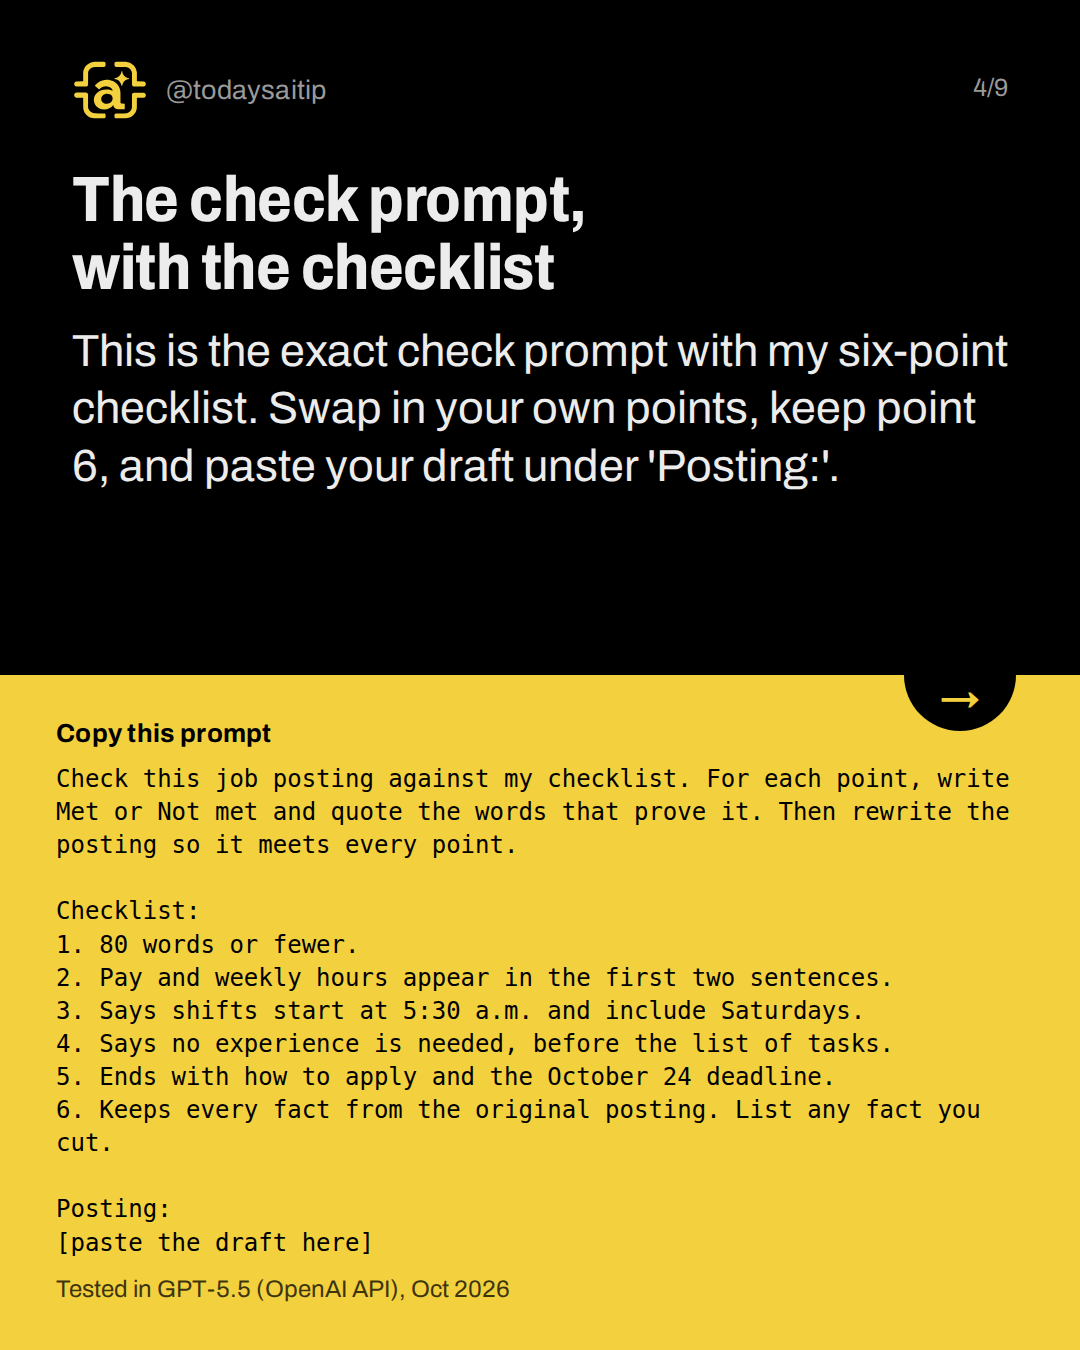
The check prompt, with the checklist
Tested in GPT-5.5 (OpenAI API), Oct 2026
This is the exact check prompt with my six-point checklist. Swap in your own points, keep point 6, and paste your draft under 'Posting:'.
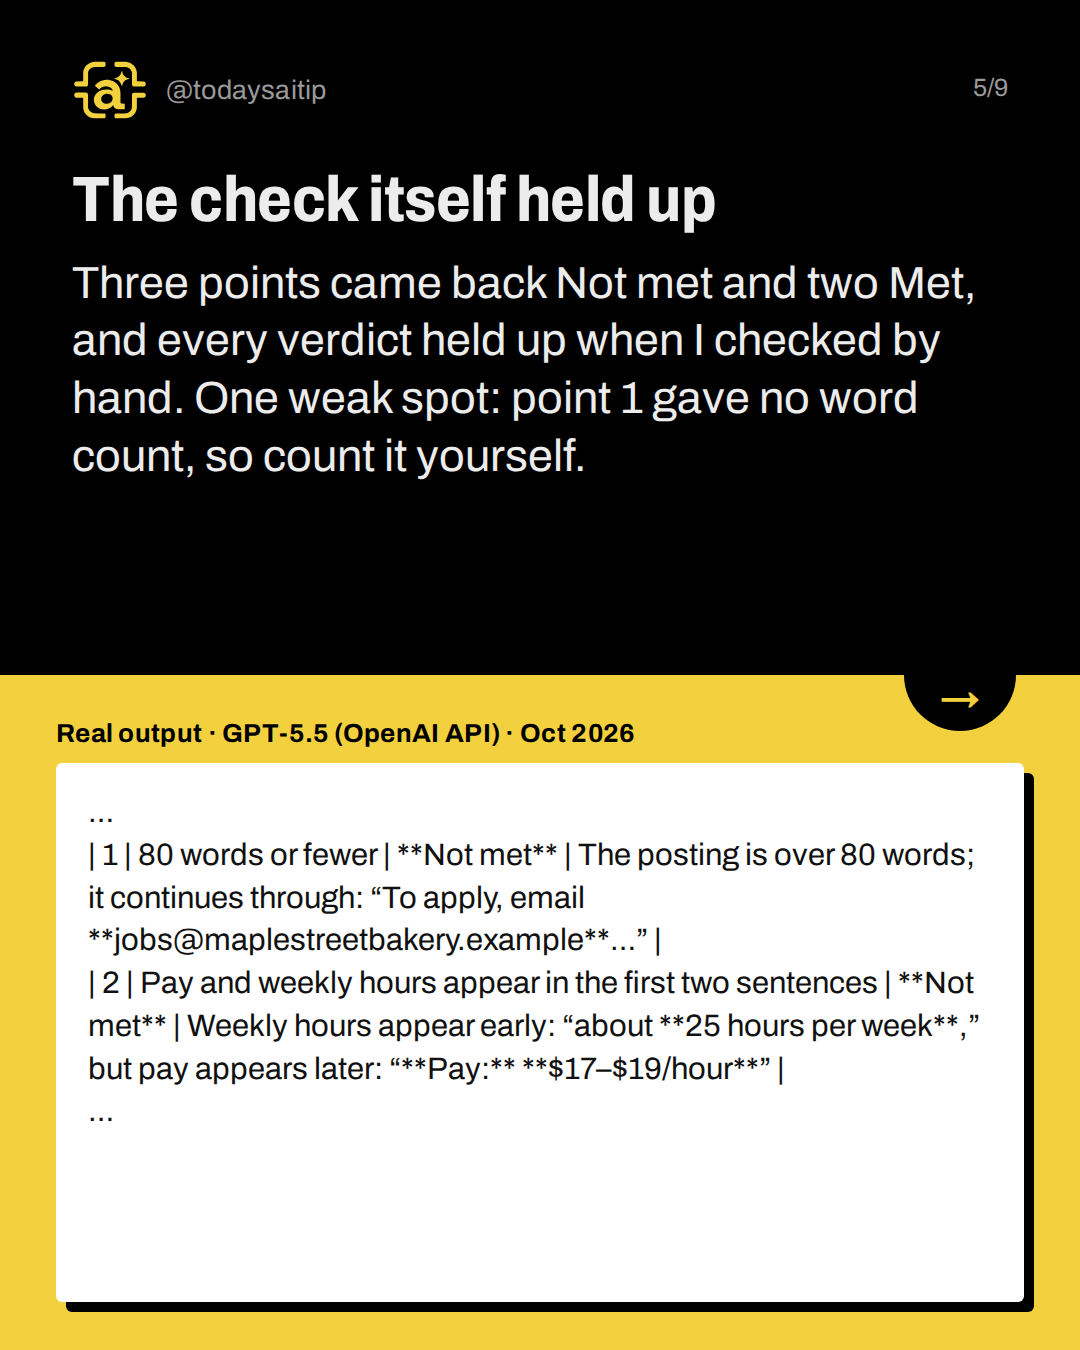
The check itself held up
Real output · GPT-5.5 (OpenAI API) · Oct 2026
Three points came back Not met and two Met, and every verdict held up when I checked by hand. One weak spot: point 1 gave no word count, so count it yourself.
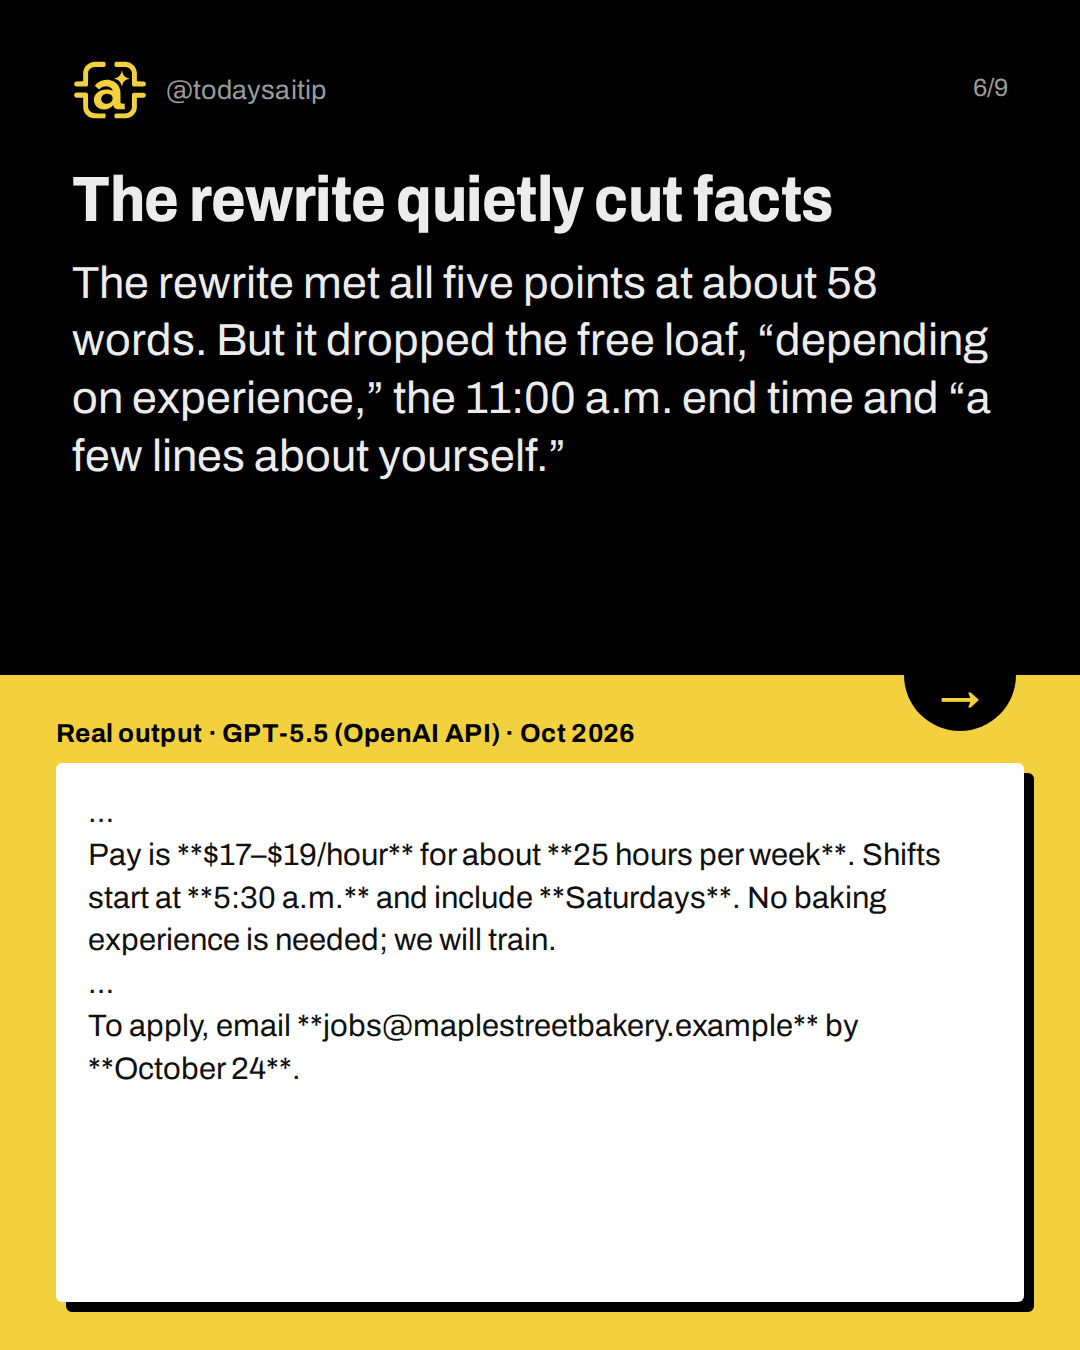
The rewrite quietly cut facts
Real output · GPT-5.5 (OpenAI API) · Oct 2026
The rewrite met all five points at about 58 words. But it dropped the free loaf, “depending on experience,” the 11:00 a.m. end time and “a few lines about yourself.”
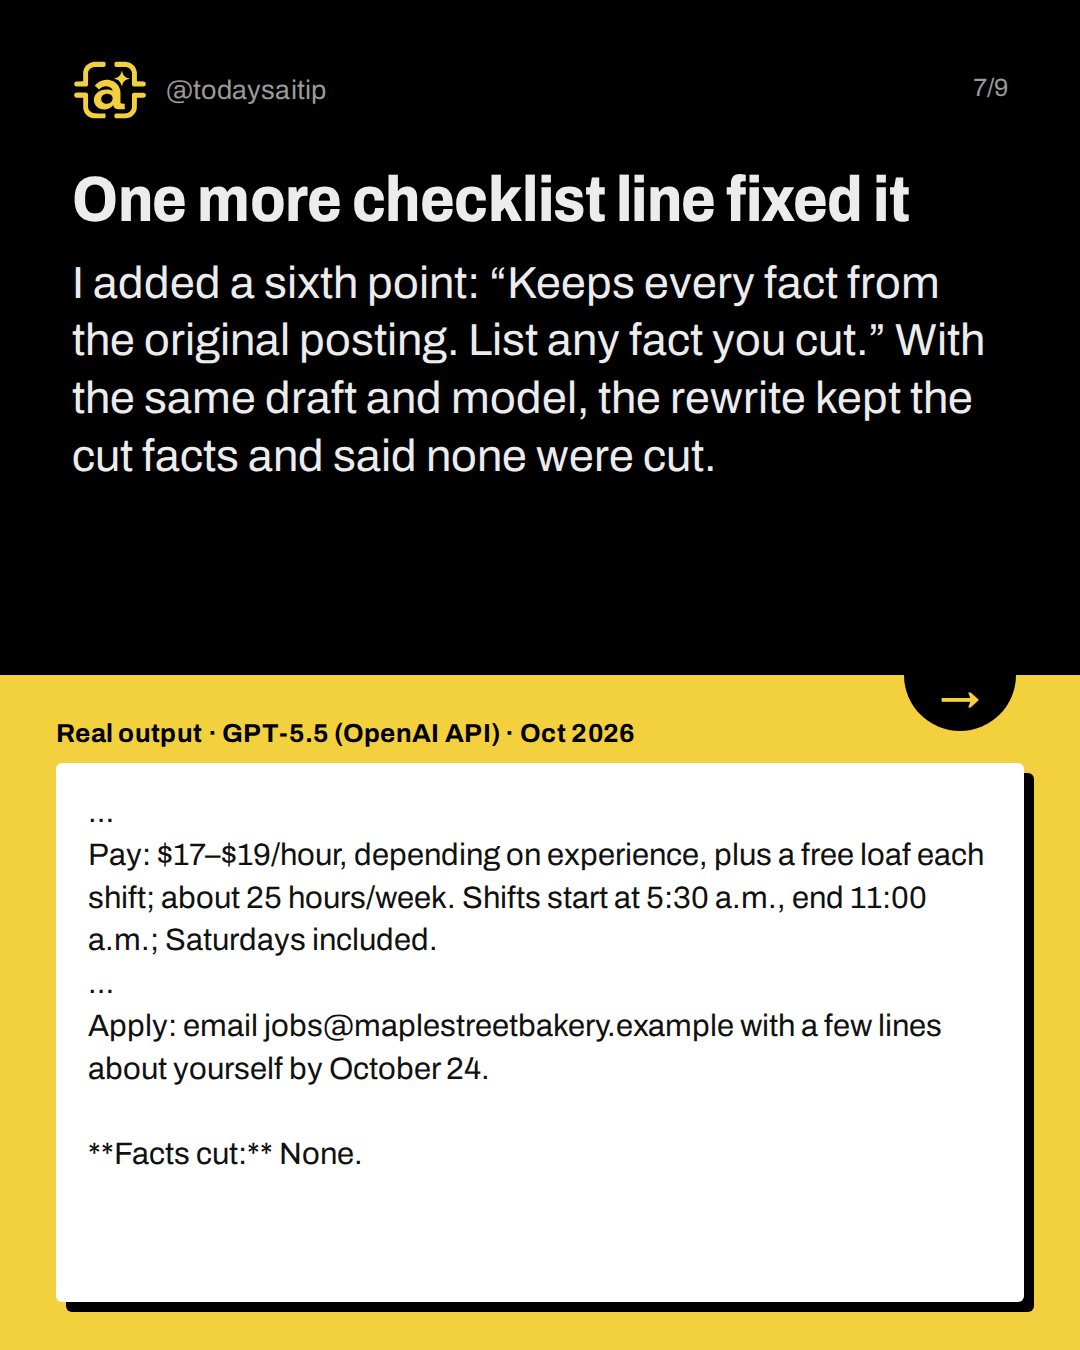
One more checklist line fixed it
Real output · GPT-5.5 (OpenAI API) · Oct 2026
I added a sixth point: “Keeps every fact from the original posting. List any fact you cut.” With the same draft and model, the rewrite kept the cut facts and said none were cut.
The routine to reuse
Let the AI draft first. Then paste your checklist and ask for Met or Not met with a quote for each point. Always add the keep-every-fact line, and count words yourself.
Try it: Run your next AI-drafted post through five points plus that sixth line.
Sources and assumptions
- Anthropic: Prompting best practices (Claude Platform Docs), section 'Chain complex prompts': "The most common chaining pattern is self-correction: generate a draft → have Claude review it against criteria → have Claude refine based on the review. Each step is a separate API call so you can log, evaluate, or branch at any point." The same page also says: "Ask Claude to self-check. Append something like 'Before you finish, verify your answer against [test criteria].'" (checked 2026-10-06)
Assumptions:
- All tests ran in GPT-5.5 through the OpenAI API (default settings, no system prompt) and are labeled 'GPT-5.5 (OpenAI API), Oct 2026', not the ChatGPT app. Two attempts to run the draft in Claude Sonnet 5.5 failed with a command error in this research session (recorded in tests.json with output null), so no Claude output exists and the post must not claim a Claude result.
- Anthropic's guide describes the pattern for Claude. The post presents it as a general technique ('Anthropic's prompting guide calls this…') and shows it tested only in GPT-5.5.
- The check step was run as a single message with the draft pasted in, so it can be copied into the same chat or a new one. In the app, readers would send it as their second message.
- Word counts are my hand counts of the plain text, without markdown, counting the heading lines and not counting '—' or '&'. Draft: about 102 words (103 if '&' counts; the model said 103). First rewrite: about 58. Second rewrite: 79 (80 if '&' counts; the model said 80).
- Checklist point 2 ('first two sentences') is a judgment call for a draft with heading lines. The model marked it Not met because pay appeared on the third line, after the hours sentence and the schedule line. I agree.
- Each step ran once (one run per prompt). Verdicts and cuts can vary between runs, so the post must say 'in my test'.
- Bakery, email address and job details are fictional sample material; the email uses the reserved .example domain.
The short version
- Let AI draft, then check it.
- Ask for Met or Not met, with quotes.
- Add keep every fact, list any cut.
- Count the words yourself.