 Today's AI Tip
I took the bullets out of my prompt. AI still used bullets.
A tip worth testing
A common tip says that if you don't want bullets back, don't write your prompt as bullets. Anthropic's Claude guide says removing markdown from a prompt can reduce markdown in the output. So I tested it.
Source: Anthropic, Claude API docs: Prompting best practices
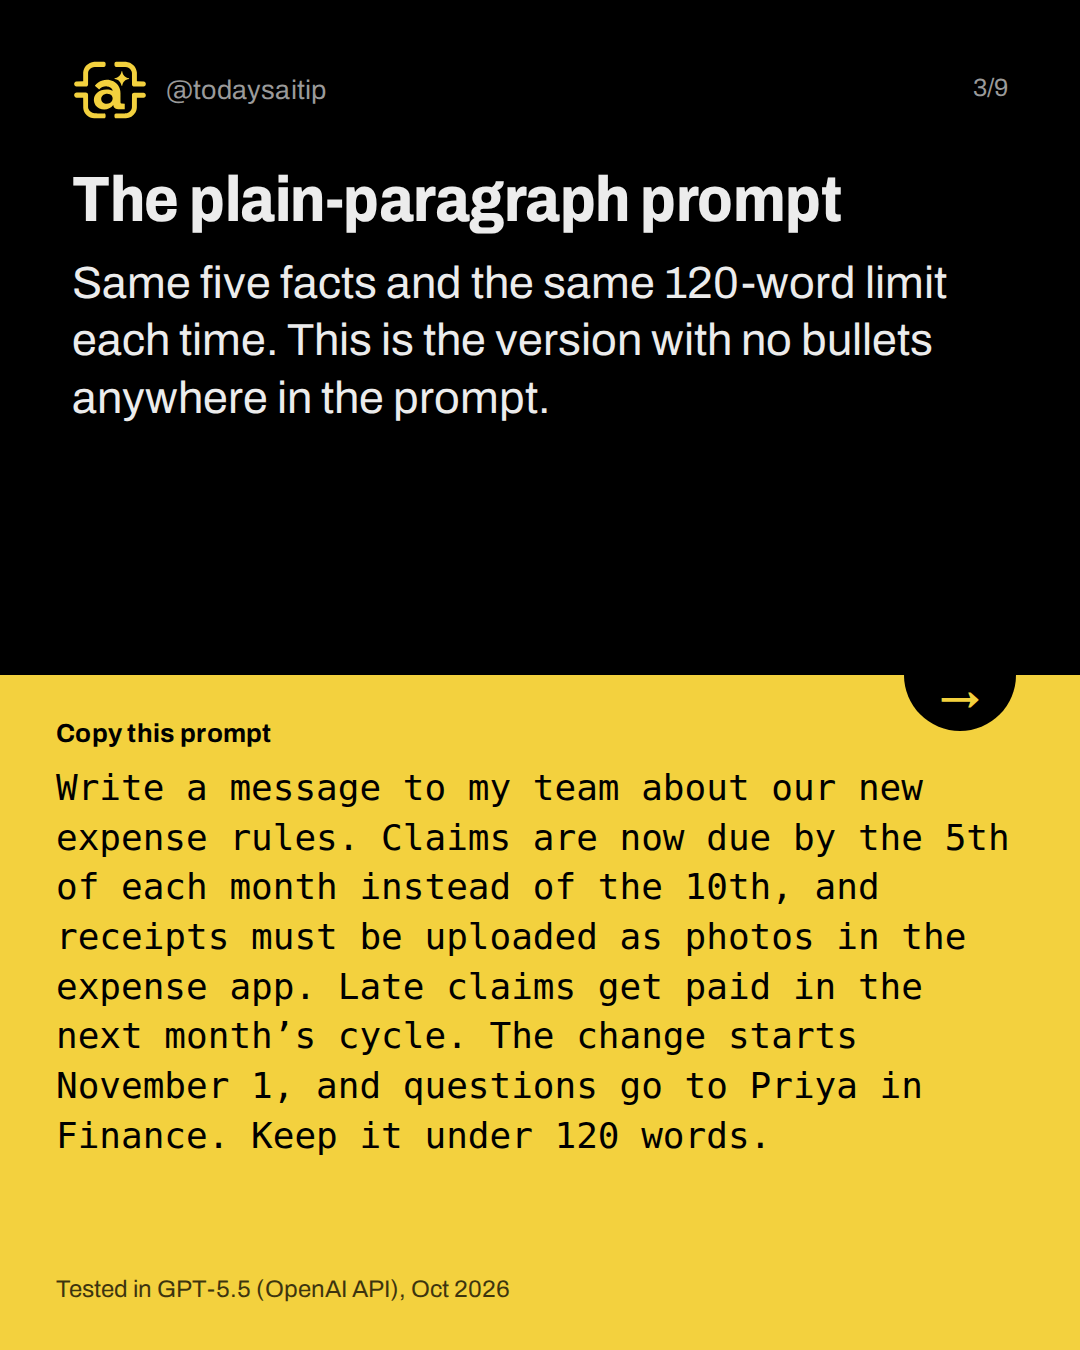
The plain-paragraph prompt
Tested in GPT-5.5 (OpenAI API), Oct 2026
Same five facts and the same 120-word limit each time. This is the version with no bullets anywhere in the prompt.
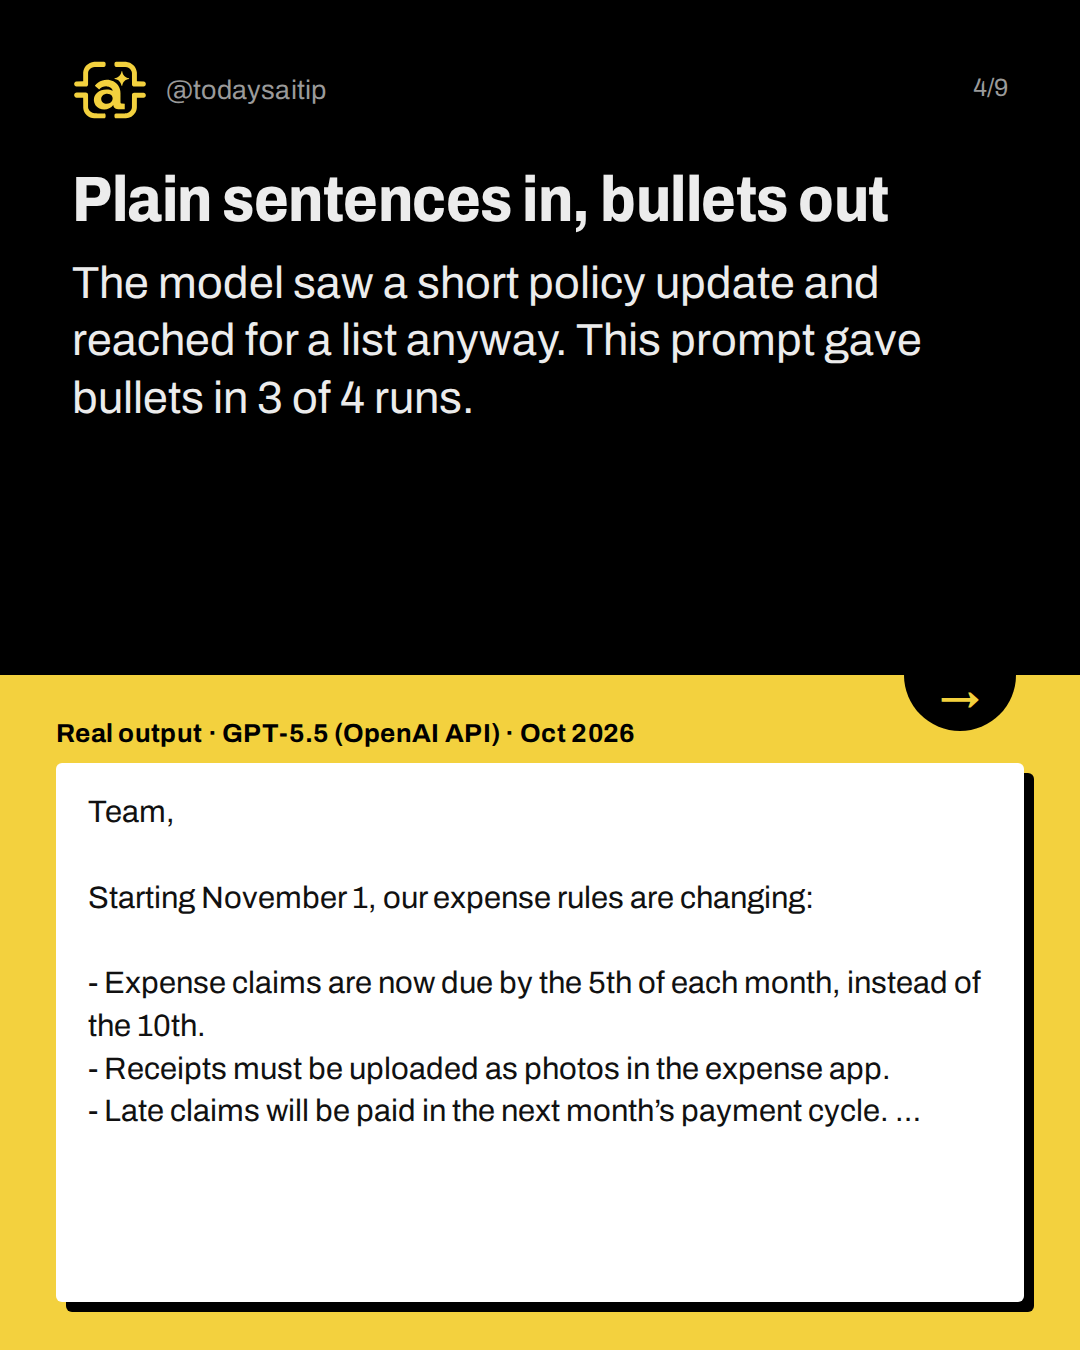
Plain sentences in, bullets out
Real output · GPT-5.5 (OpenAI API) · Oct 2026
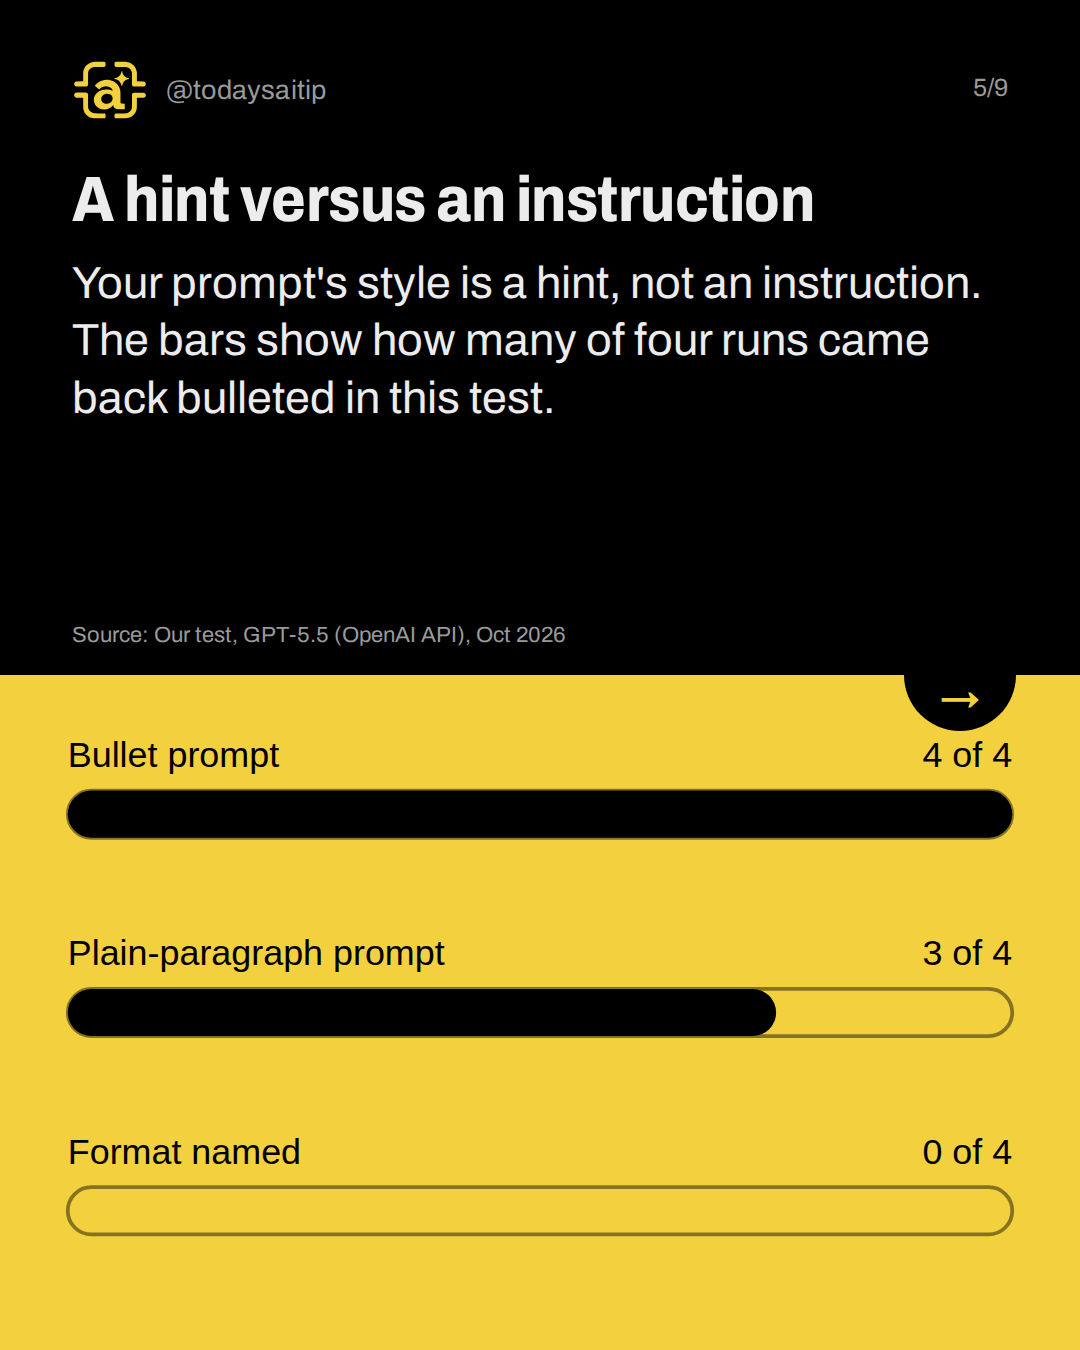
The model saw a short policy update and reached for a list anyway. This prompt gave bullets in 3 of 4 runs.
A hint versus an instruction
Your prompt's style is a hint, not an instruction. The bars show how many of four runs came back bulleted in this test.
Source: Our test, GPT-5.5 (OpenAI API), Oct 2026
The fix: name the format
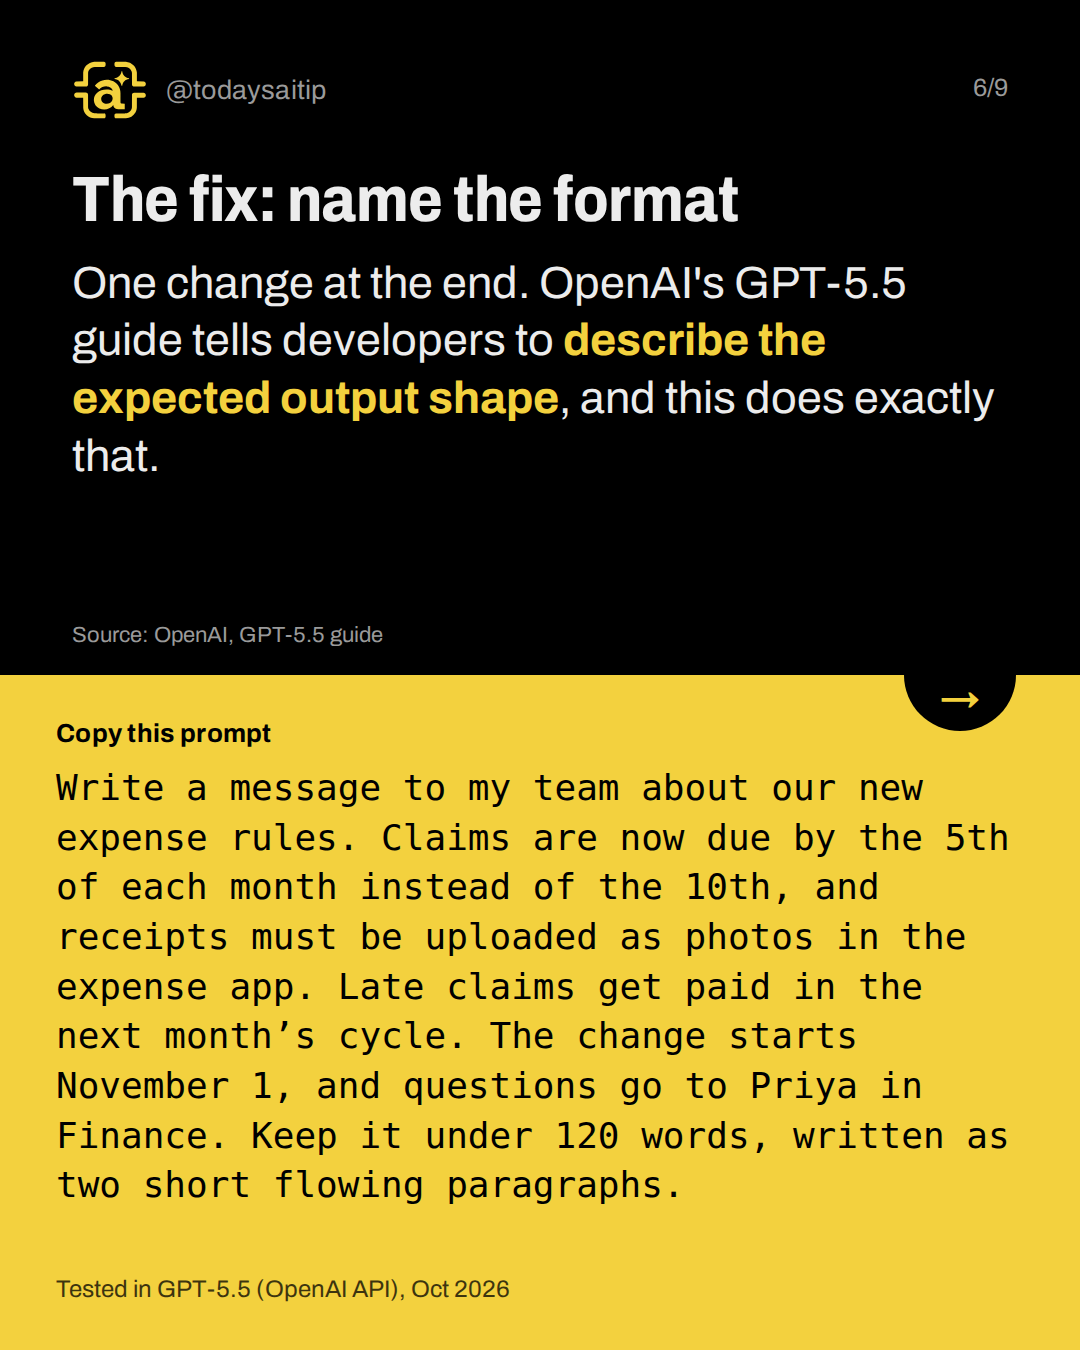
Tested in GPT-5.5 (OpenAI API), Oct 2026
One change at the end. OpenAI's GPT-5.5 guide tells developers to describe the expected output shape, and this does exactly that.
Source: OpenAI, GPT-5.5 guide
Two paragraphs, four out of four
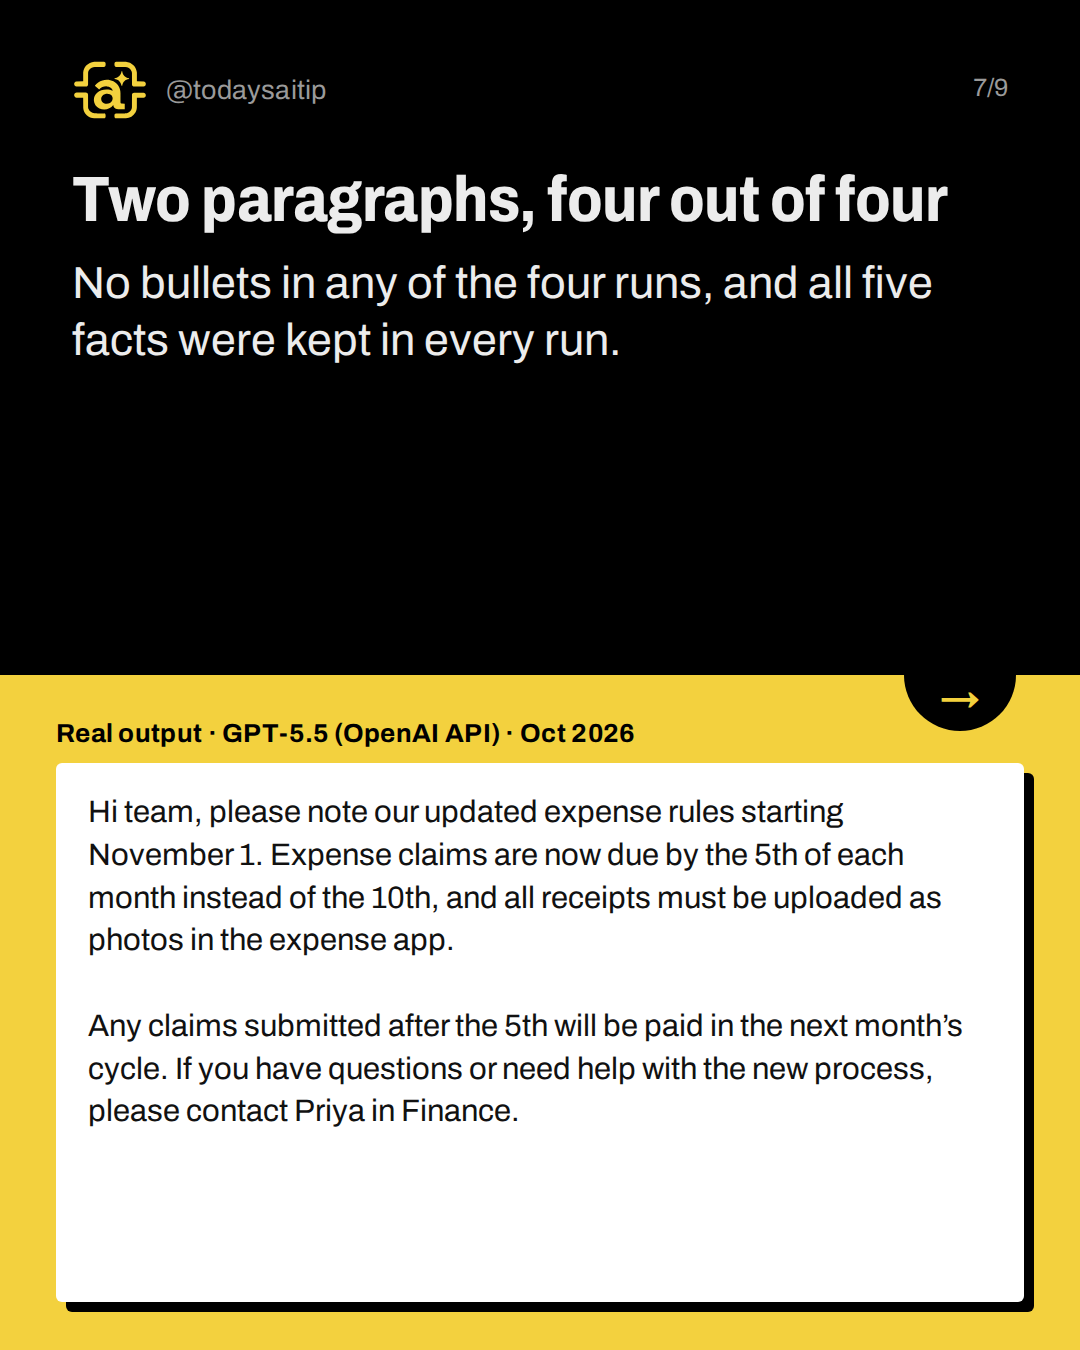
Real output · GPT-5.5 (OpenAI API) · Oct 2026
No bullets in any of the four runs, and all five facts were kept in every run.
What this test doesn't prove
Four runs, one model, one message: a tendency, not a guarantee. This was GPT-5.5 through the API, not Claude or the ChatGPT app. Still skim the facts before sending.
Try it: Add 'written as two short paragraphs' to your next message request.
Sources and assumptions
- Prompting best practices: Control the format of responses (Claude API docs, Anthropic): Section 'Control the format of responses', point 3 'Match your prompt style to the output you want': 'The formatting style used in your prompt might influence Claude's response style. If you are still experiencing steerability issues with output formatting, try matching your prompt style to the output style you want as closely as possible. For example, removing markdown from your prompt can reduce the volume of markdown in the output.' Point 1: Instead of 'Do not use markdown in your response', try 'Your response should be composed of smoothly flowing prose paragraphs.' (checked 2026-10-25)
- GPT-5.5 guide (OpenAI API docs): OpenAI's guidance to 'describe the expected output shape', and its sample instruction to 'Respect formatting preferences from the user. If they ask for a terse answer, minimal formatting, no bullets, no headers, or a specific structure, follow that preference unless there is a strong reason not to.' (These are developer-facing guide lines, not a guarantee of how the model behaves.) (checked 2026-10-25)
Assumptions:
- The test ran in GPT-5.5 through the OpenAI API (label 'GPT-5.5 (OpenAI API)', Oct 2026) with no system prompt; the ChatGPT app has its own system instructions and may format differently.
- Claude could not be run in this research session (every claude test errored, recorded with null output), so the post does not claim any Claude result. The 'match your prompt style' tip is quoted from Anthropic's Claude guide as the advice being tested, and the test is in GPT-5.5.
- Counts come only from the recorded runs in record.tests: bullets-1..4 (bulleted prompt) gave bullets 4/4; paragraph-1..4 (plain prompt) gave bullets 3/4 (paragraph-1 used short one-sentence paragraphs with no bullets); say-format-1..4 gave two paragraphs with no bullets 4/4.
- 'All five facts kept' was checked by hand against each say-format output: Nov 1 start, 5th instead of 10th, receipts as photos in the expense app, late claims paid next month's cycle, questions to Priya in Finance.
- The sample (an expense-rule team message, Priya in Finance) is fictional.
- Four runs per version is a small sample; the slides say 'in this test' and call it a tendency, not a guarantee.
The short version
- A plain-paragraph prompt still got bullets 3 of 4 times
- Your prompt's style is only a hint
- Name the format you want
- Two paragraphs came back 4 of 4 times