 Today's AI Tip
Splitting a bill with AI? Ask for the table, not just the answer.
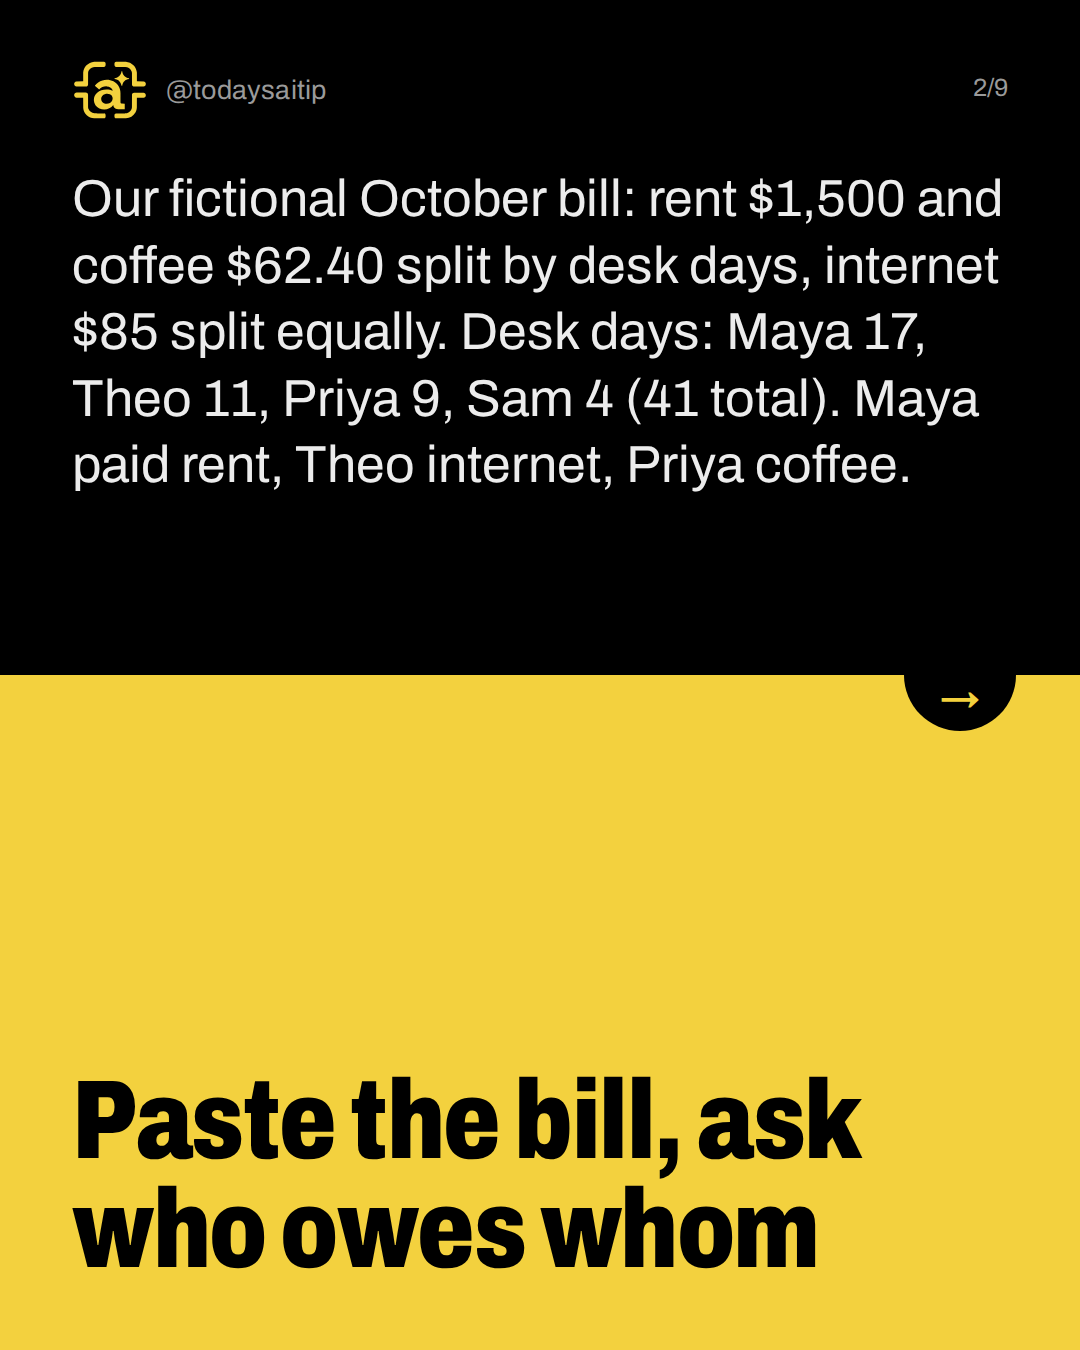
Paste the bill, ask who owes whom
Our fictional October bill: rent $1,500 and coffee $62.40 split by desk days, internet $85 split equally. Desk days: Maya 17, Theo 11, Priya 9, Sam 4 (41 total). Maya paid rent, Theo internet, Priya coffee.
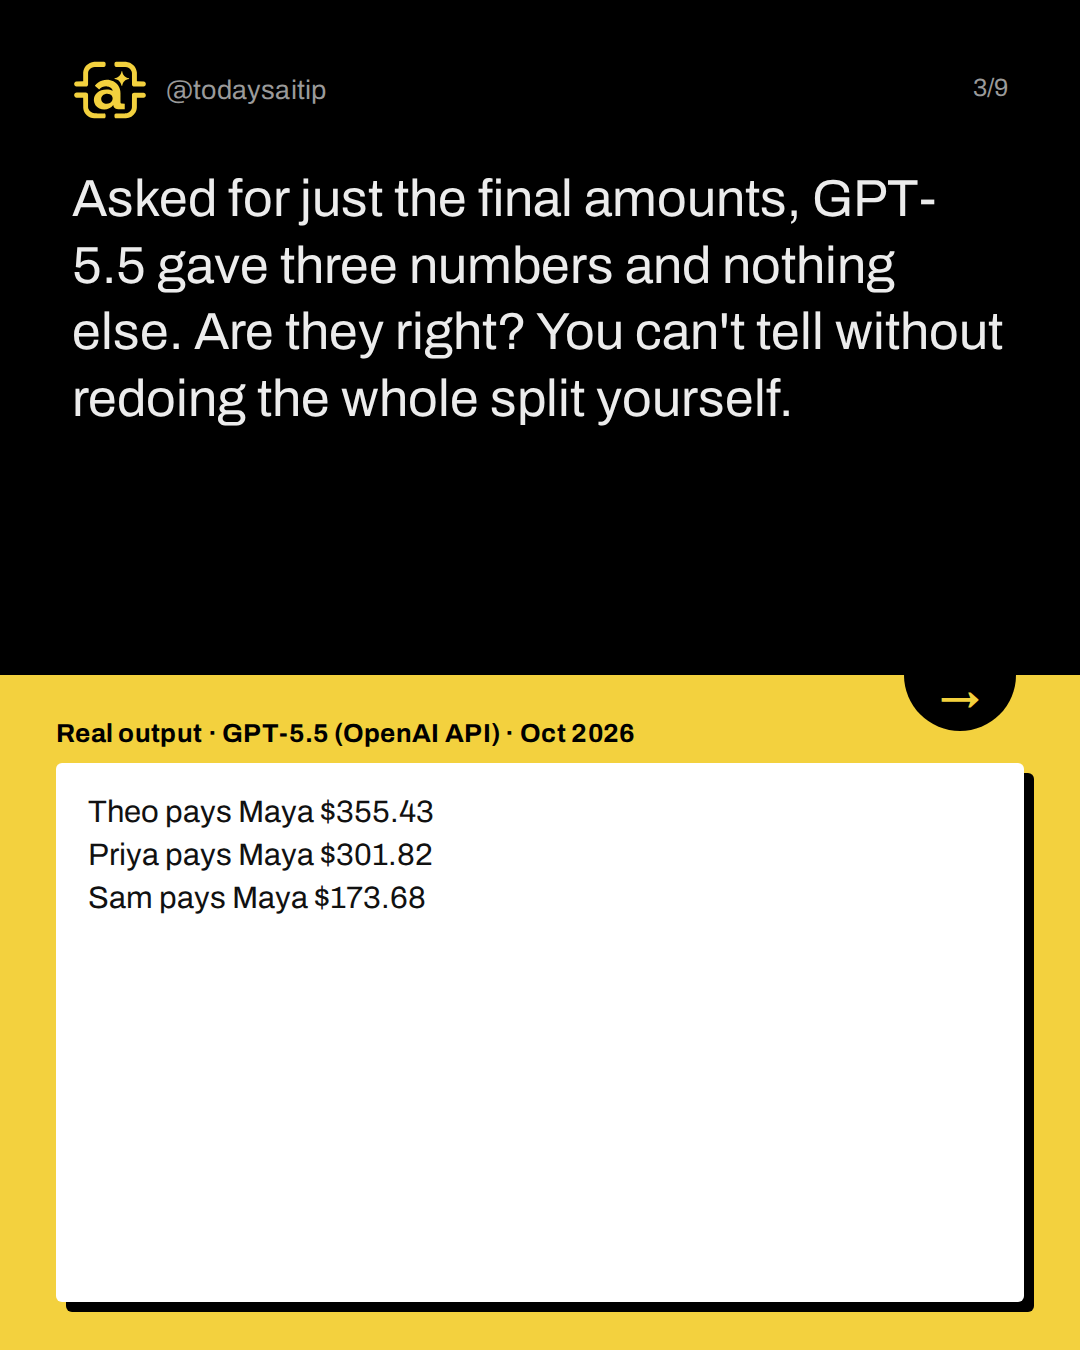
Real output · GPT-5.5 (OpenAI API) · Oct 2026
Asked for just the final amounts, GPT-5.5 gave three numbers and nothing else. Are they right? You can't tell without redoing the whole split yourself.
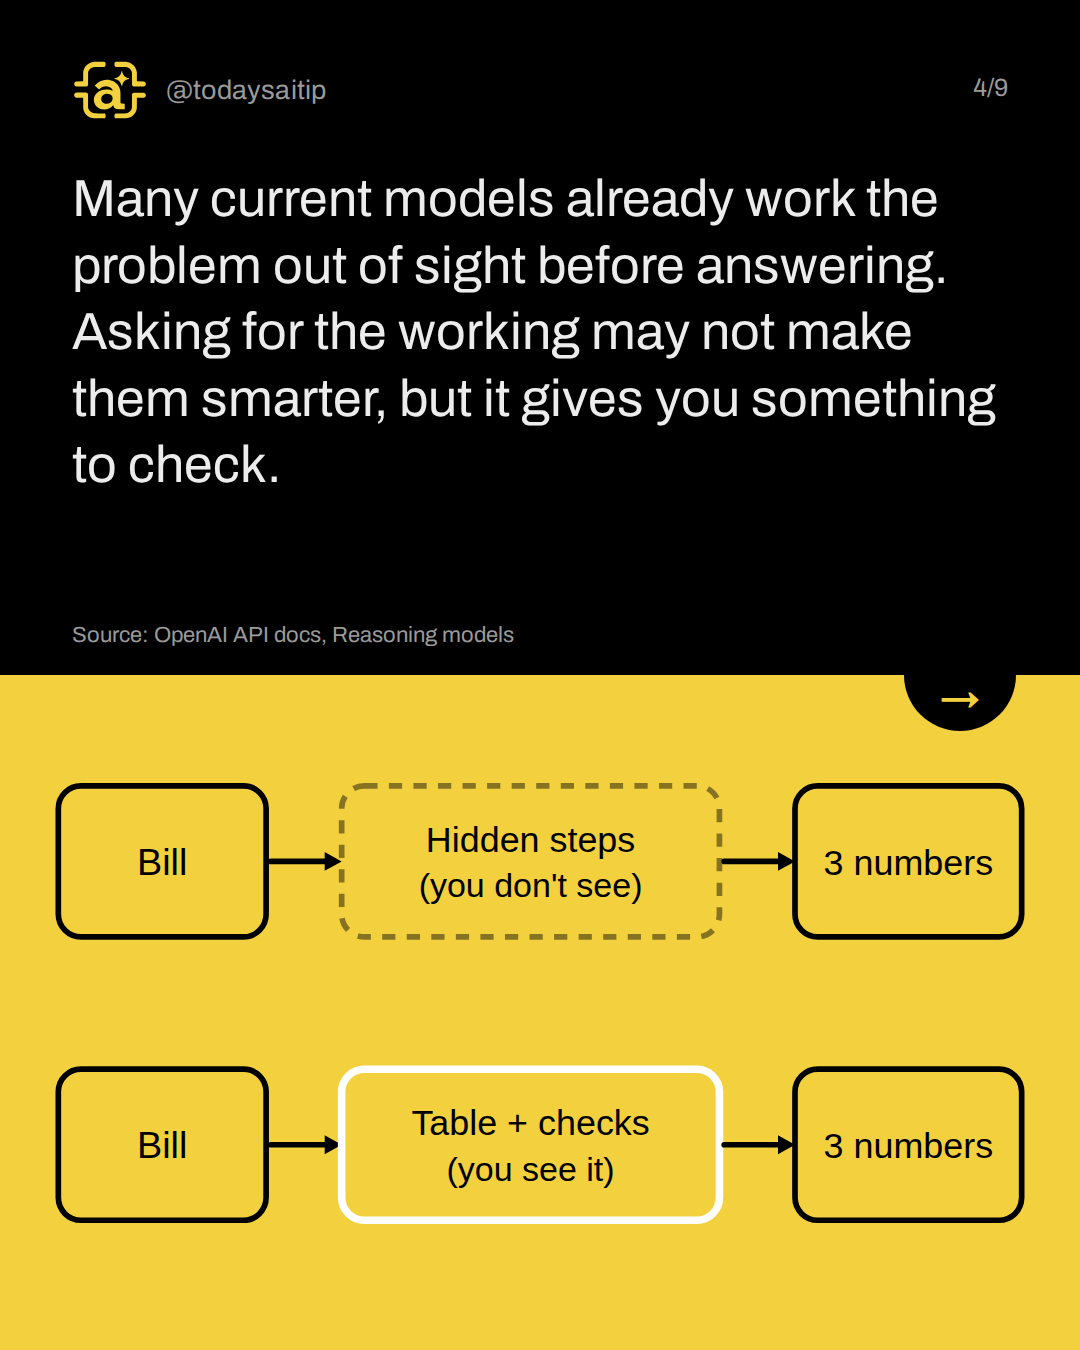
Many current models already work the problem out of sight before answering. Asking for the working may not make them smarter, but it gives you something to check.
Source: OpenAI API docs, Reasoning models
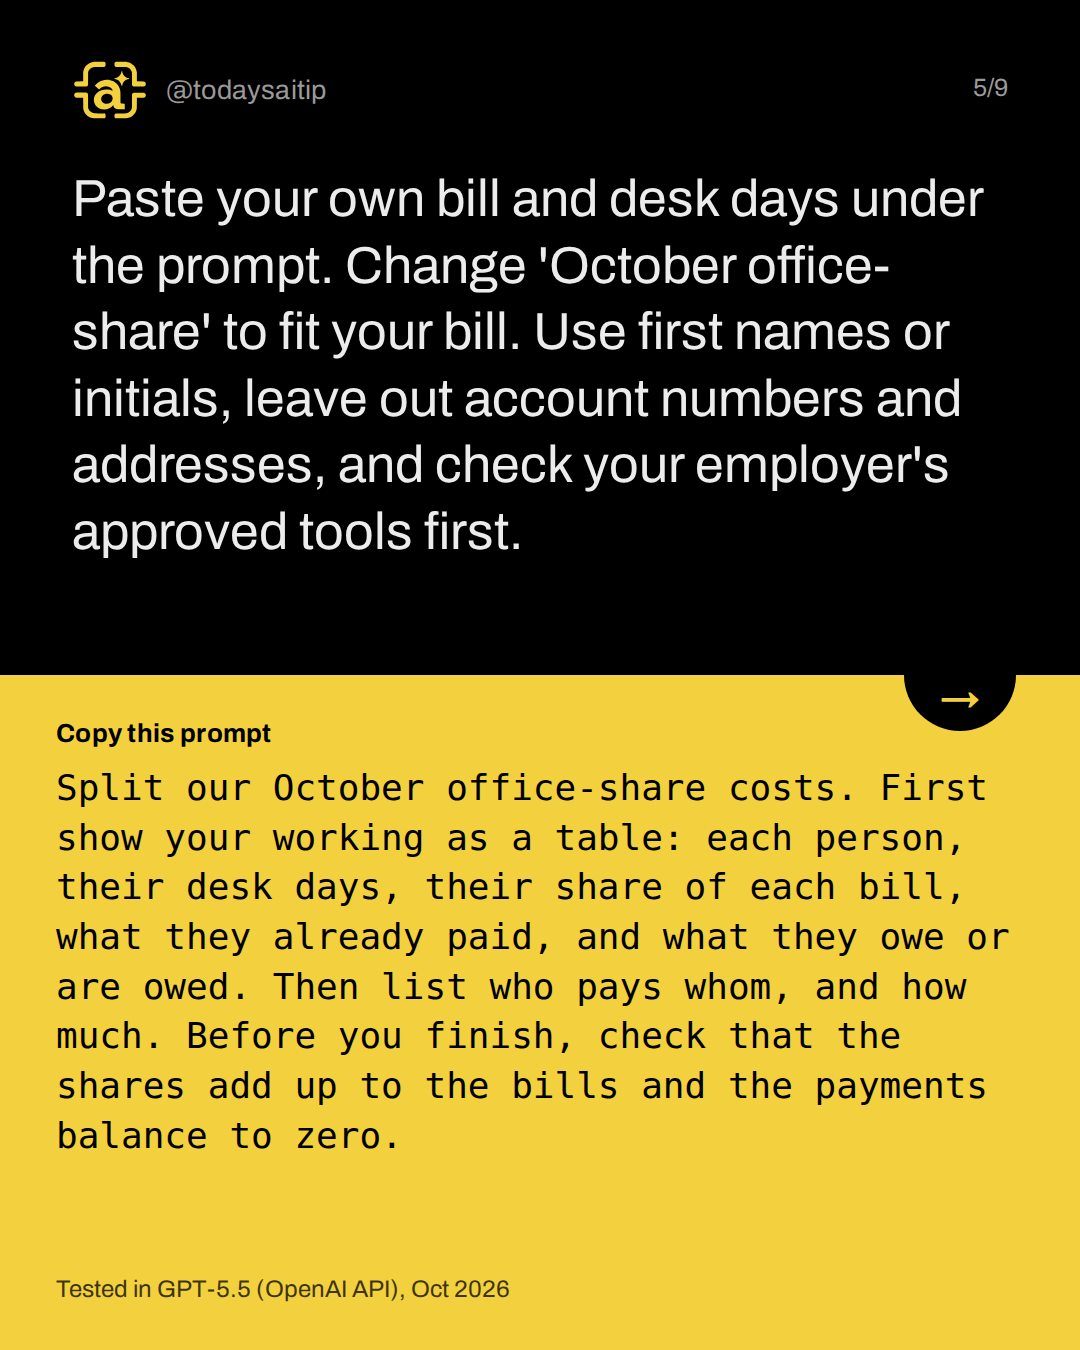
Tested in GPT-5.5 (OpenAI API), Oct 2026
Paste your own bill and desk days under the prompt. Change 'October office-share' to fit your bill. Use first names or initials, leave out account numbers and addresses, and check your employer's approved tools first.
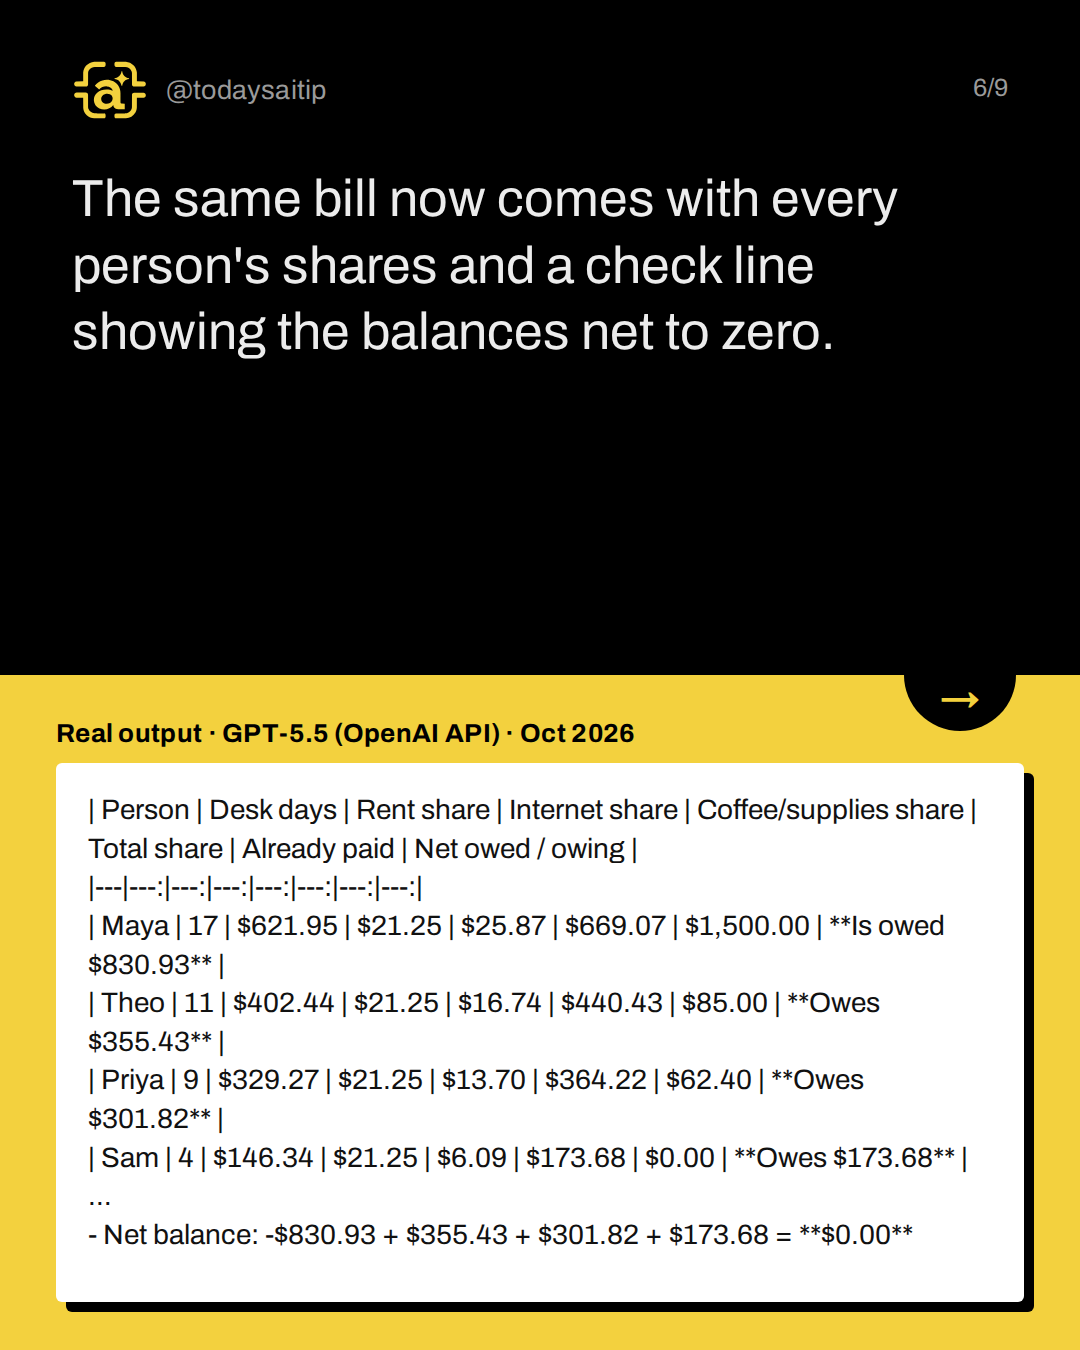
Real output · GPT-5.5 (OpenAI API) · Oct 2026
The same bill now comes with every person's shares and a check line showing the balances net to zero.
I redid one row by hand
Theo's rent share: $1,500 × 11 ÷ 41 = $402.44 (about $36.59 a day; don't round the day rate before multiplying). Add $21.25 and $16.74, subtract the $85 he paid, and he owes $355.43. It matched.
Check four things: the table's inputs match your bill, each share column adds up, the balances net to $0, and one row works by hand. A wrong desk-day count would still balance.
Try it: Paste your last shared bill with the prompt and check one row.
Sources and assumptions
- Prompting best practices (Claude API docs, Anthropic): On Claude Fable 5.1, Fable 5, Opus 5.5, Opus 5 and Sonnet 5.5, Anthropic says to 'rely on thinking instead' of manual chain-of-thought, and that 'a prompt that asks the model to write out its reasoning, for example in <thinking> tags, may be declined'. It also says: 'Ask Claude to self-check. Append something like "Before you finish, verify your answer against [test criteria]." This catches errors reliably, especially for coding and math.' The page does not contain the queue note's 'Claude needs to output its thinking' wording, so the post must not use it. (checked 2026-10-29)
- Reasoning models (OpenAI API docs): Reasoning models 'use internal reasoning tokens before producing a response', and 'reasoning tokens are not visible via the API'. OpenAI recommends giving models 'a clear goal, strong constraints, and an explicit output contract without prescribing every intermediate step'. (checked 2026-10-29)
- Our own GPT-5.5 test runs (record.tests: answer-only-gpt, show-working-gpt, hard-answer-only-gpt, hard-show-working-gpt): The verbatim outputs on the slides. Run 2026-10-30 UTC through the OpenAI API (model gpt-5.5). (checked 2026-10-29)
Assumptions:
- All names and bills are fictional: Maya, Theo, Priya and Sam, rent $1,500, internet $85, coffee $62.40, desk days 17/11/9/4 (41 total).
- Shares are rounded to the cent. The rounded rent shares happen to add up to exactly $1,500.00 and the coffee shares to $62.40, so no rounding penny is left over in this example. Other bills may leave one, and the table would show it.
- Each prompt was run once per bill on GPT-5.5 via the OpenAI API with default settings. One run doesn't show how often answer-only output is wrong. In our test it was never wrong.
- Claude could not be run from this research session: the claude CLI failed on every call, including a 'Say hi' probe. tests.json still holds two Claude entries with output null, and they must not appear on any slide. The post names only GPT-5.5 (OpenAI API), and prompt_tools must not mention Claude.
- The Anthropic doc lines are context about why showing working won't necessarily boost accuracy on current models. They don't back any claim about GPT-5.5, and GPT-5.5's accuracy claims come only from our test.
The short version
- Both prompts were correct in our test
- Only the table could be checked
- Make sure shares add up to each bill
- Check one row by hand, then settle up