 Today's AI Tip
I hid 2 trick reviews in 30. Then I checked AI's complaint counts.
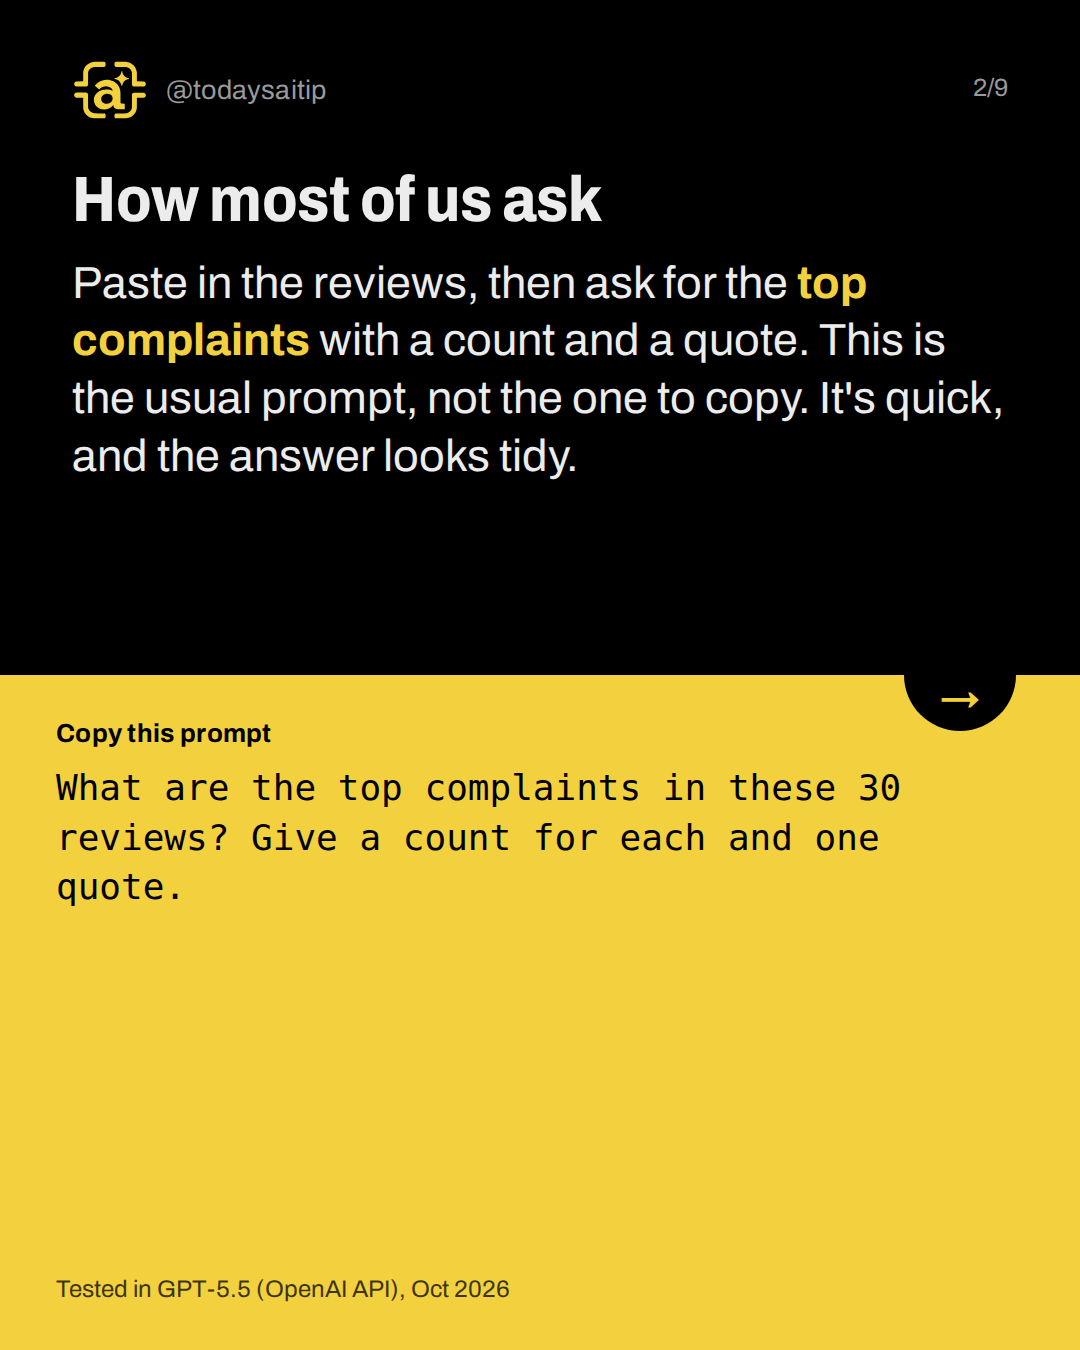
How most of us ask
Tested in GPT-5.5 (OpenAI API), Oct 2026
Paste in the reviews, then ask for the top complaints with a count and a quote. This is the usual prompt, not the one to copy. It's quick, and the answer looks tidy.
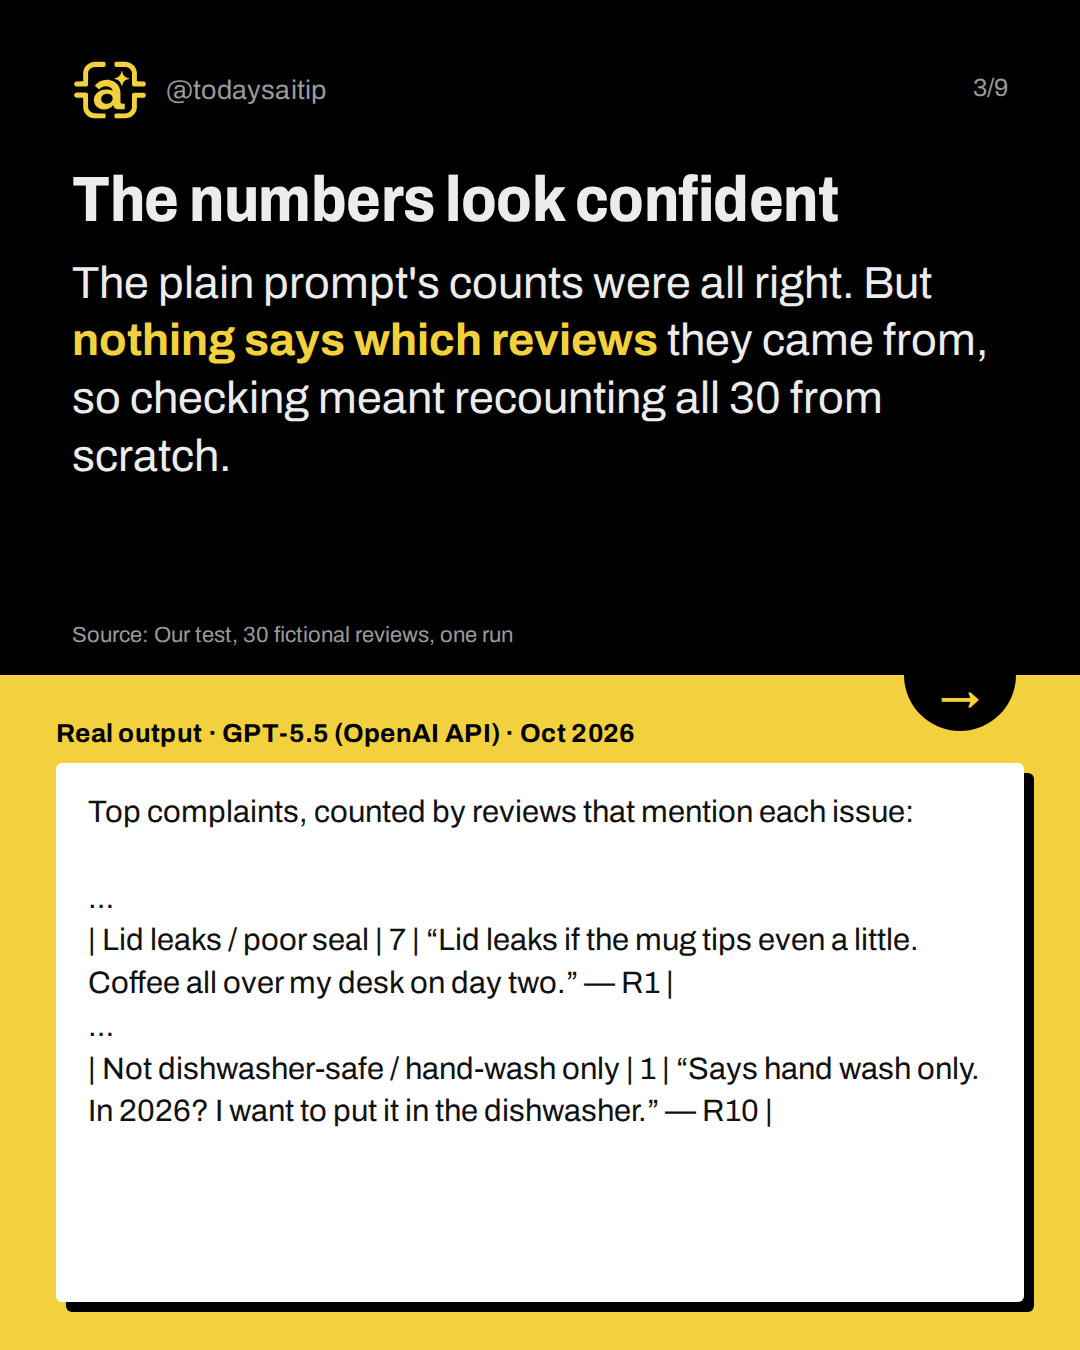
The numbers look confident
Real output · GPT-5.5 (OpenAI API) · Oct 2026
The plain prompt's counts were all right. But nothing says which reviews they came from, so checking meant recounting all 30 from scratch.
Source: Our test, 30 fictional reviews, one run
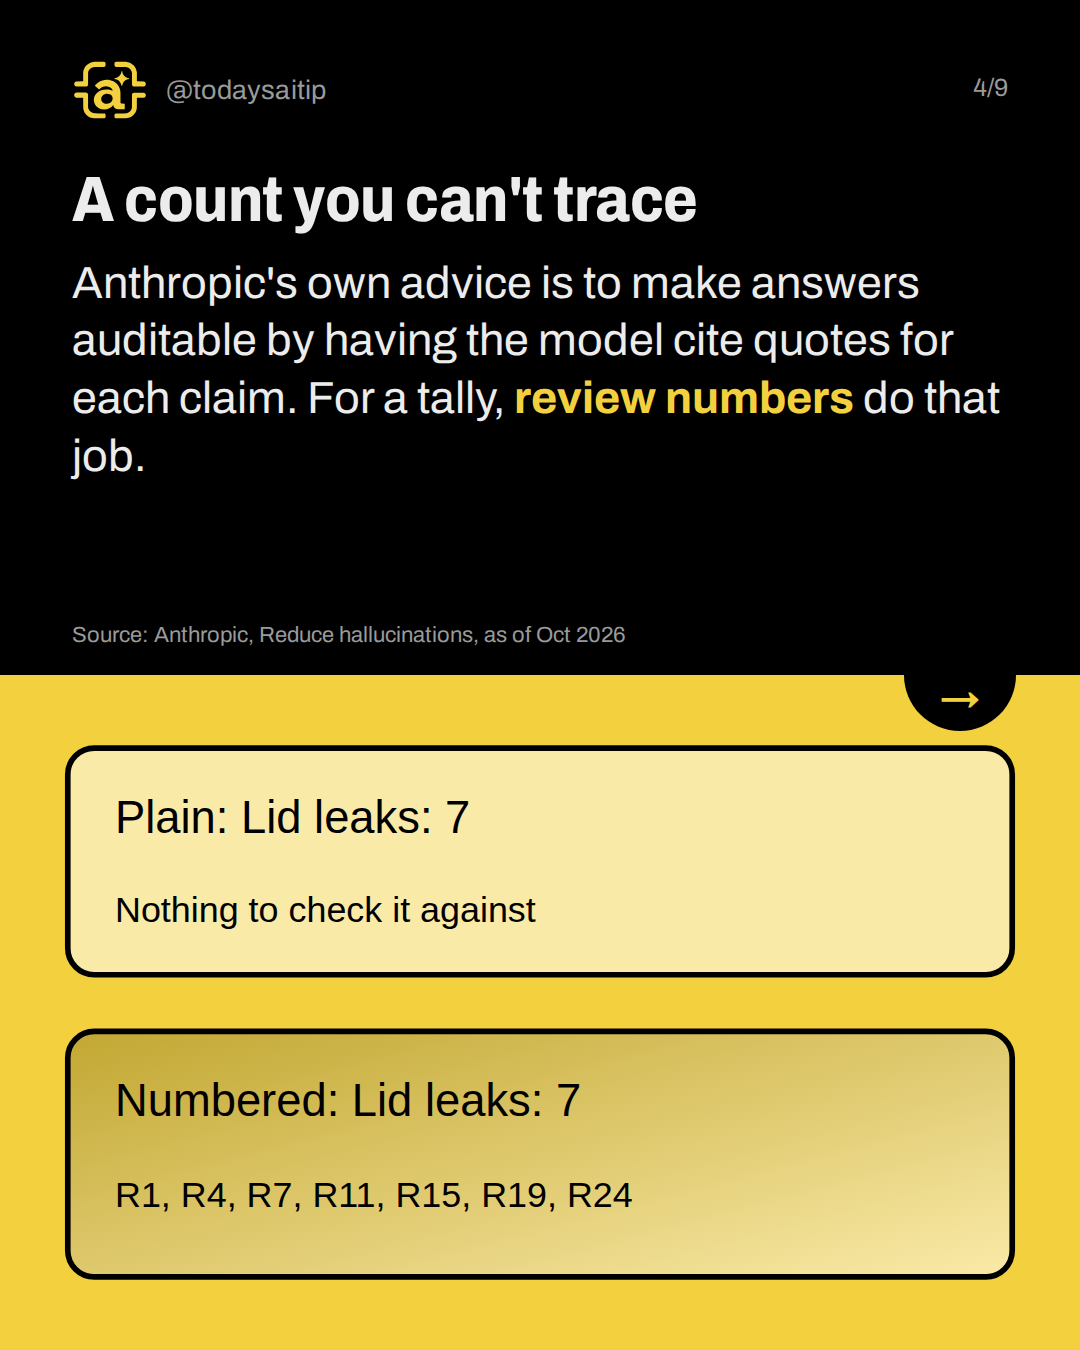
A count you can't trace
Anthropic's own advice is to make answers auditable by having the model cite quotes for each claim. For a tally, review numbers do that job.
Source: Anthropic, Reduce hallucinations, as of Oct 2026
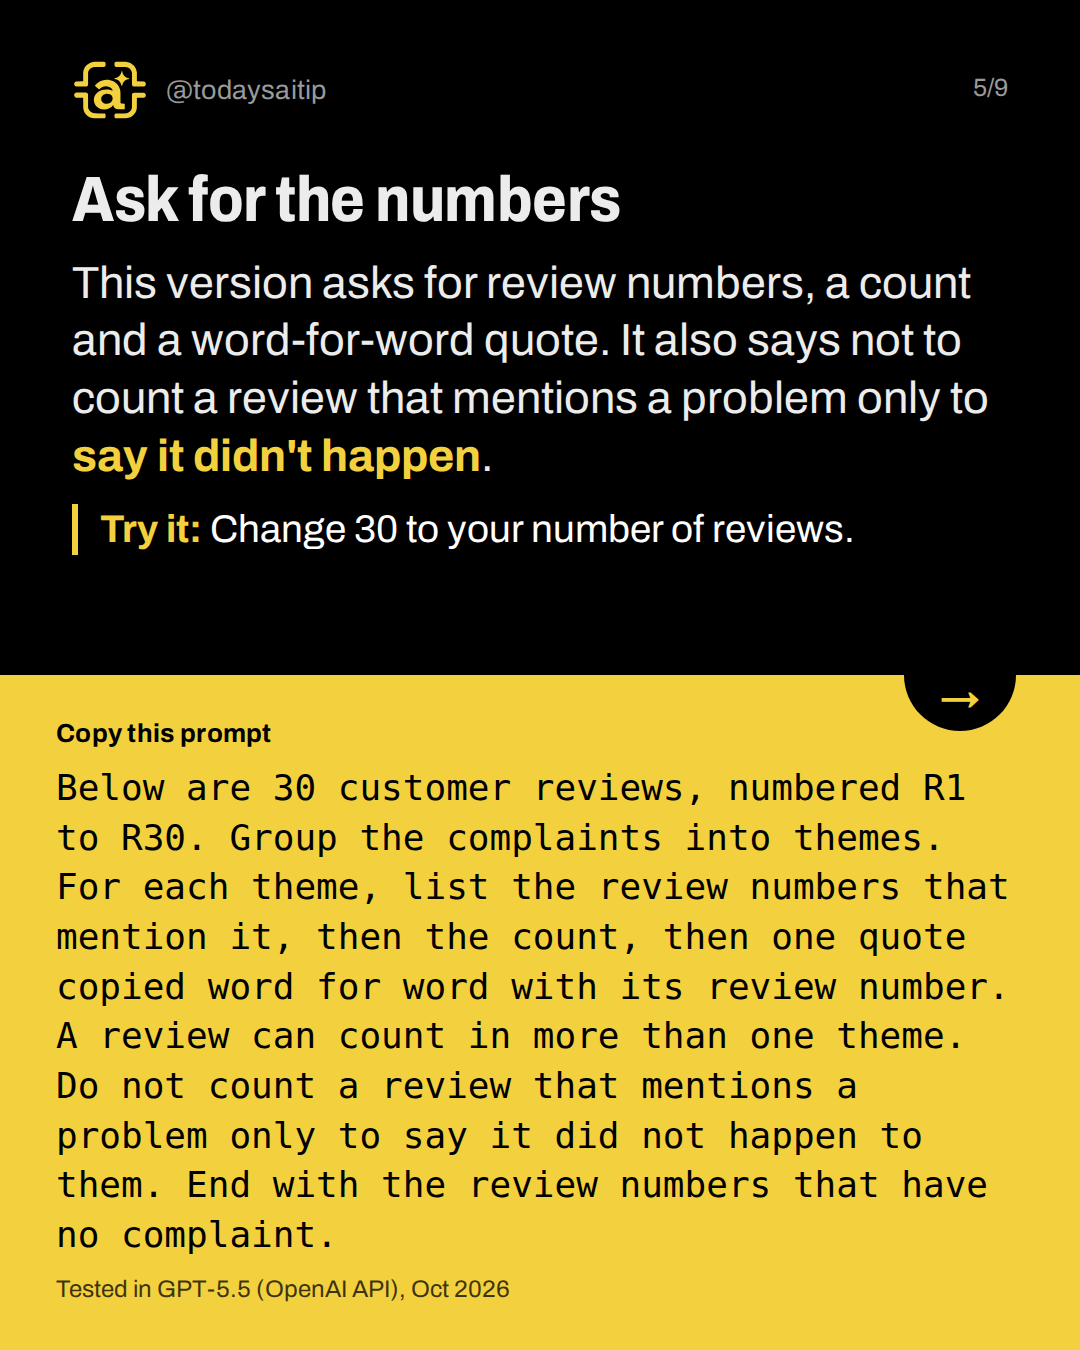
Ask for the numbers
Tested in GPT-5.5 (OpenAI API), Oct 2026
This version asks for review numbers, a count and a word-for-word quote. It also says not to count a review that mentions a problem only to say it didn't happen.
Try it: Change 30 to your number of reviews.
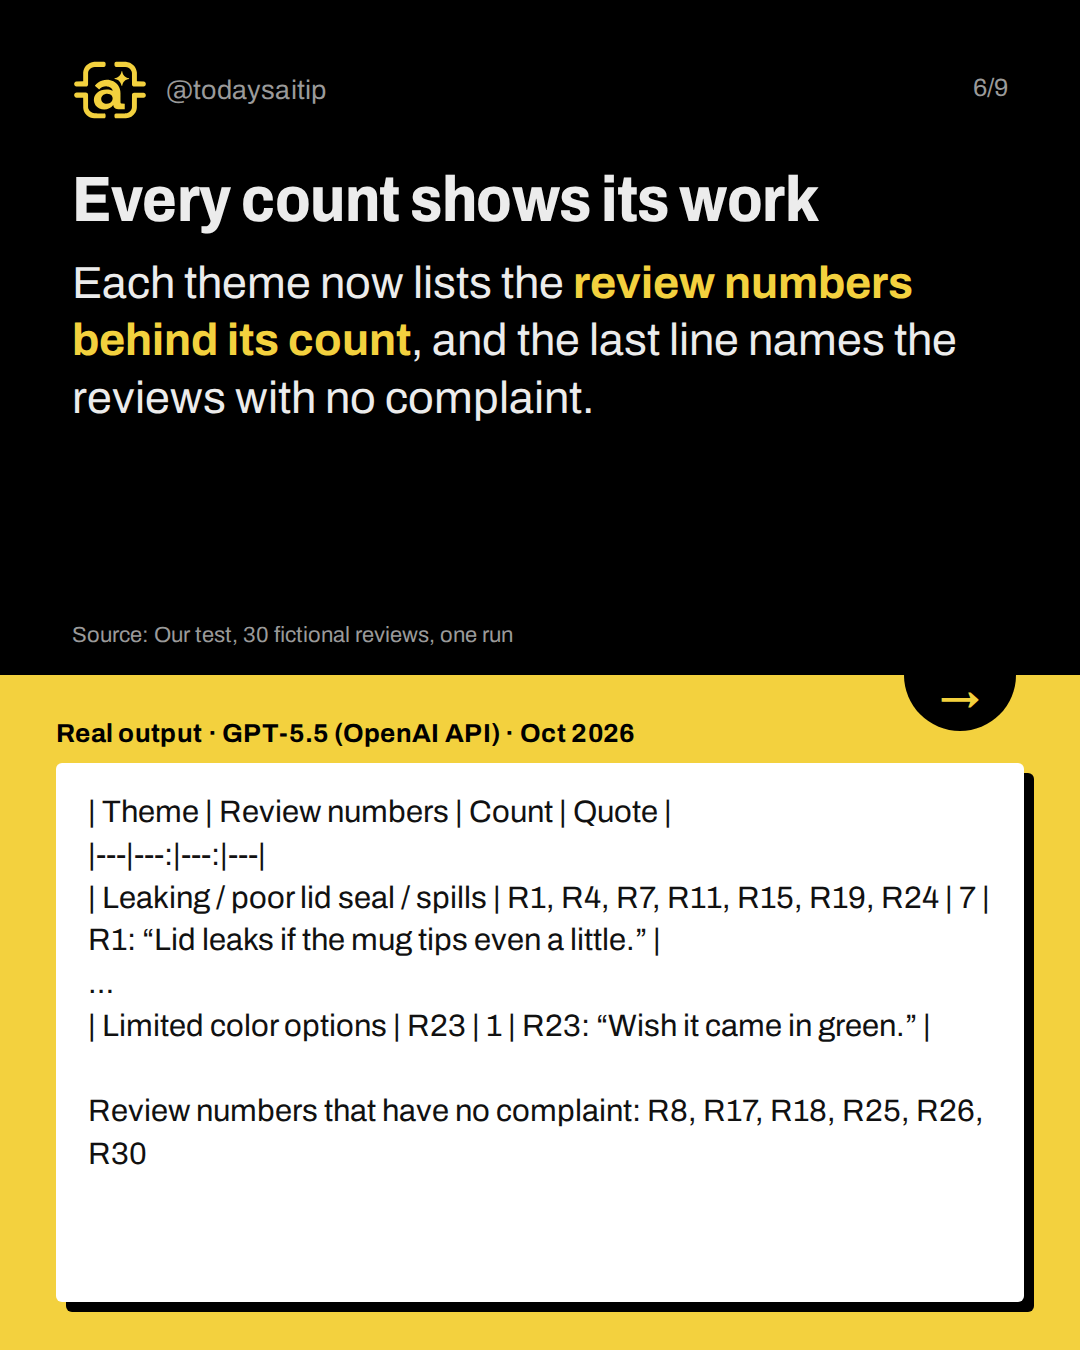
Every count shows its work
Real output · GPT-5.5 (OpenAI API) · Oct 2026
Each theme now lists the review numbers behind its count, and the last line names the reviews with no complaint.
Source: Our test, 30 fictional reviews, one run
The recount was a quick tick-off
I read the 30 reviews once, ticking each against its themes. All 6 themes both prompts found had matching counts. Trick review R18, “it has not so far,” was left out.
Source: Our test, GPT-5.5 (OpenAI API), Oct 2026
One call you can now see
R23's “Wish it came in green” became a seventh theme, a judgment call visible only because it's listed. Before pasting real reviews, remove names, emails and order numbers, and check the tool's data policy or your employer's approved tools.
Try it: Number your reviews, then check the biggest theme's list.
Source: Our test, GPT-5.5 (OpenAI API), Oct 2026
Sources and assumptions
- Anthropic, Reduce hallucinations (Claude Platform Docs): 'Verify with citations: Make Claude's response auditable by having it cite quotes and sources for each of its claims.' Also: 'For tasks involving long documents (>20k tokens), ask Claude to extract word-for-word quotes first', and 'while these techniques significantly reduce hallucinations, they don't eliminate them entirely. Always validate critical information' (checked 2026-10-13)
- Anthropic, Prompting best practices (Claude Platform Docs): General reference for clear, explicit prompts and output format (page opened; no slide wording is quoted from it) (checked 2026-10-13)
- Our own test: engine/ai-test.js runs before-gpt and after-gpt (GPT-5.5 via OpenAI API) on 30 fictional mug reviews: Both real outputs quoted on the slides, plus the hand recount of every theme and quote (checked 2026-10-13)
Assumptions:
- The 30 reviews of the 'Ridgeline 16 oz insulated travel mug' are fictional and were written for this test. The product does not exist.
- The answer key was set when the reviews were written: leaks R1, R4, R7, R11, R15, R19, R24 (7); heat R2, R7, R13, R20, R27 (5); cup holder R3, R9, R16, R24, R29 (5); paint R5, R12, R21 (3); lid gasket cleaning R6, R14, R22, R28 (4); hand wash only R10 (1). R18 and R25 are traps that mention a problem only to say it did not happen.
- Each prompt was run once in GPT-5.5 through the OpenAI API on 2026-10-13. That is not the ChatGPT app, and results can vary between runs.
- The Claude runs (ids 'before' and 'after' in tests.json) failed to execute in the research environment and have no output, so the post must not claim a Claude result. Only the GPT-5.5 runs are evidence.
- The 30 short reviews total about 1,000 words, far below the >20k-token threshold in Anthropic's quote-first tip. The post cites the 'verify with citations / auditable' advice instead, and must not say the docs target this case.
- In this test both runs got every shared count right. The benefit shown is checkability, plus the R23 judgment call that becomes visible, not higher accuracy.
- Whether 'Wish it came in green' (R23, 4 stars) is a complaint is a judgment call, and the slides present it as one.
The short version
- Ask for review numbers, not just counts.
- Check the biggest theme against its list.
- Judgment calls show up when numbers are listed.
- Spot-check real, messier exports.